Wildo.ai Coming soon

Shared code, shared checks

Exercise common application mechanisms through integration scenarios, permission checks and regression tests.

Integration scenarios · access boundaries · regressions

A business application carries responsibilities long after its first release. Permissions change, integrations evolve and a routine action can affect data, notifications and evidence in several places.

Wildo brings recurring mechanisms into a shared engine, where their behavior can be tested and maintained together. Your application’s decisions and customer journeys need their own checks on top of that foundation.

An application examined through its mechanisms, journeys and recorded evidence.

Confidence comes from the behavior you can observe

Exercise the connection, not only the function

A permission check matters when a request reaches it. Organization isolation matters when another organization tries to read the same record. An integration matters when its protocol and the application meet.

Wildo’s testing surfaces include focused checks and application scenarios around these boundaries. The purpose is to examine the behavior a product depends on, including the surrounding services and failure paths.

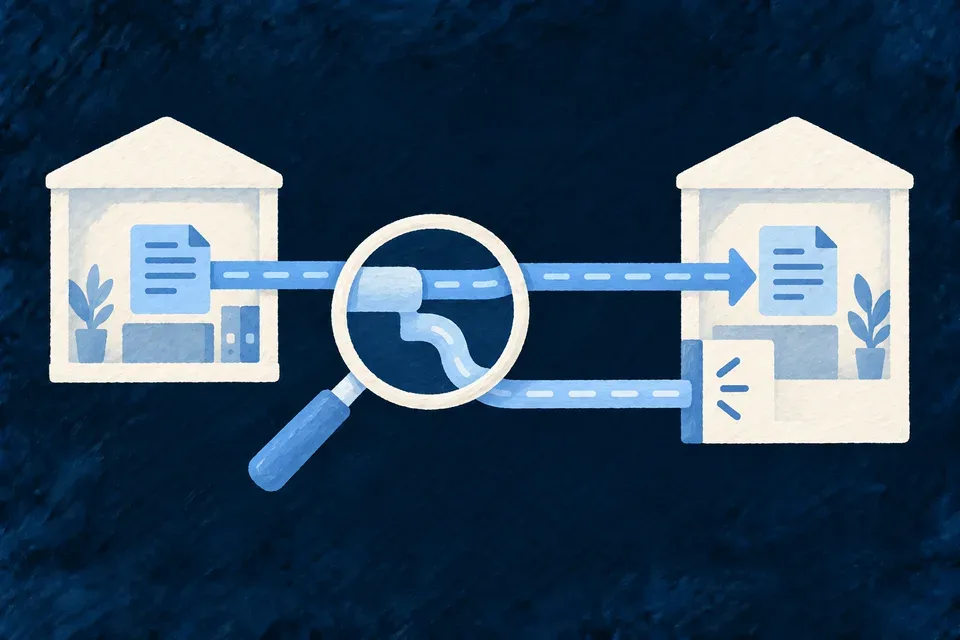
Two ivory organization rooms: a permitted blue path reaches its own record while a second path stops at the other room's boundary.
  • Behavior across real connections: Scenarios exercise cooperating application components and service boundaries.
  • Allowed and refused actions: Both outcomes help demonstrate an intended access boundary.
  • Failure paths deserve attention: Tests examine what happens when the surrounding conditions change.

Maintain the common work in one place

When applications use the same engine mechanism, a correction has a shared home. Tests can pin the intended behavior beside the implementation, and subsequent engine changes can be checked against it.

That creates a practical maintenance advantage. Each application can concentrate its own verification on its business rules, configuration and journeys, while deliberately adopting and validating changes to the common foundation.

A maintained blue structural joint beneath an application, beside a notebook containing repeatable path sketches and small check marks.
  • Corrections have a home: Shared implementation gives recurring behavior one maintenance location.
  • Keep intended behavior pinned: Regression checks accompany changes to common engine mechanisms.
  • Validate your actual application: Adopt updates with checks for your configuration and journeys.

Make AI’s work reviewable

An AI-produced change needs more than convincing prose. Structured contracts, repository checks, task-specific verification and observable results give the team concrete material to review.

The factory’s working methods connect implementation with validation instructions and recorded outcomes. This keeps verification part of the work, rather than something the next conversation has to reconstruct.

An application change sketch placed beside its contract sheet and an evidence notebook on a tidy workbench.
  • Evidence beyond persuasive prose: Contracts and observable outcomes give reviewers concrete material.
  • Verification travels with work: Tasks can carry relevant checking instructions and context.
  • Keep results available: Recorded outcomes support inspection after an implementation attempt.

Treat responsibility as part of the product

Access control, audit evidence, privacy and operational behavior affect ordinary product decisions. They belong in the architecture and its checks, alongside the features people see.

Shared mechanisms make those responsibilities easier to address consistently. The application’s actual policies, operating environment and obligations still determine what must be demonstrated. Explore application specifications for how product intent stays connected to that work.

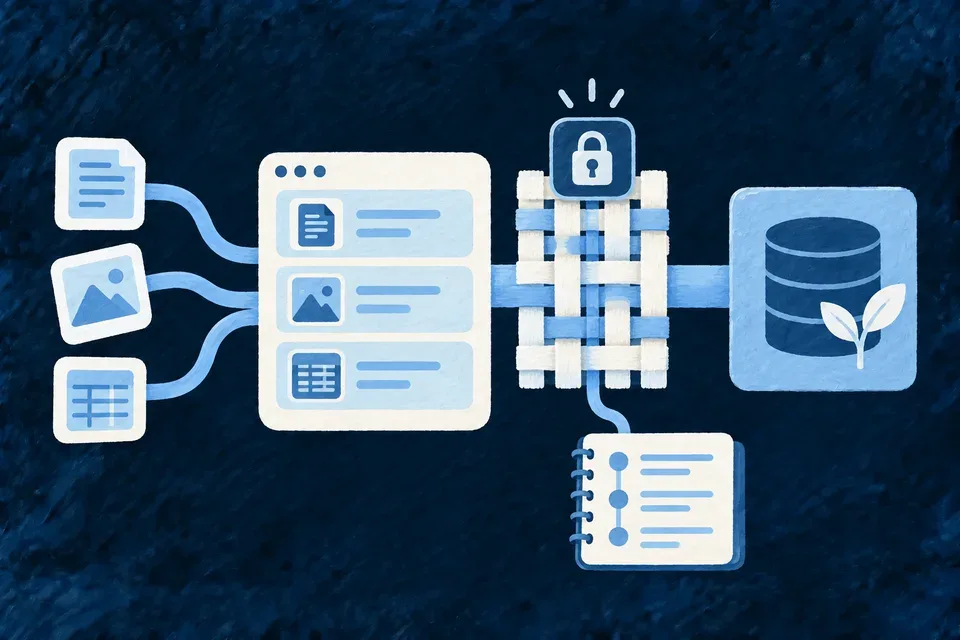
A business application cutaway showing everyday record movement, an access boundary and a small audit trail notebook integrated in the same structure.
  • Controls in ordinary behavior: Access, privacy and audit affect everyday product decisions.
  • Shared mechanisms for diligence: Common engineering helps address recurring responsibilities consistently.
  • Evidence for your commitments: Actual policies and operating conditions determine what needs demonstration.

Example: Check both sides of an access boundary

An organization administrator completes an allowed action. A person from another organization attempts the corresponding access and is refused. Checking both outcomes makes the intended boundary observable; a rejection alone could also mean that the feature is broken for everyone.

Match the evidence to the claim

Use more than one level of verification

EvidenceWhat it helps establish
Types and schema checksDeclared contracts fit their consumers
Focused behavior testsA mechanism responds correctly to specific inputs and failures
Application scenariosConnected components behave as expected in the exercised environment
Logs and recorded outcomesThe run reached its intended actions and exposed relevant failures
Product acceptanceThe implemented journey satisfies the application’s requirements

One level does not replace the others. A green typecheck says nothing about whether a customer can complete an entire journey. An application scenario proves the path and environment it exercised.

Test allowed behavior as well as refusal

The engine behavior scenario registry distinguishes required engine and platform surfaces. Scenarios include organization isolation, SSO, SCIM, webhooks and SIEM behavior. The SSO isolation scenario establishes working routes for two organizations before probing the cross-organization boundary.

The backend log gate also examines the run’s log window for fatal and critical failures. This provides another way to detect a run that appears successful while its backend reports trouble.

Verify the application you actually ship

Add checks for custom operations, role configuration, external integrations and the journeys that matter to your customers. When adopting an engine update, exercise those paths against the application’s configuration and environment.

See playbooks and choreography for how implementation work can carry its verification context. The presence of a test is useful evidence of engineering intent; its execution and result are what establish the behavior of a particular revision.

Explore the underlying mechanisms

Testing harnesses

The suites and doubles that prove the engine works against a running stack.

The engine

End-to-end scenarios

A running stack

Customer double

Client integration double

Vendor simulators

The suites and doubles that prove the engine works against a running stack.

Harnesses and doubles that prove the engine works

Customer-infrastructure test double Tool

A standalone service that stands in for a customer's identity provider, directory, security-event sink and webhook receiver, so enterprise integrations can be proven end to end without a real customer.

A running fleet standing in for the systems a customer would operate — an identity provider, a directory that pushes users in, a security-event collector, a webhook receiver — so an isolation claim is asserted from ROWS rather than inferred.

Limits

It carries no business logic and no application data. It proves that the right protocol exchange reached the right origin; whether the application then did the right thing with it is asserted on the application side.

Two faces need the same toolchain the framework’s own assertion validation needs, including a compiled helper. When that helper is missing, the failure surfaces as an invalid signature rather than as a missing dependency — a misleading error for the person meeting it.

Its own notes state that the package imports no framework packages. That is no longer literally true: it takes a type-only import of the shared spine so the fleet satisfies the same observation contract every other surface does. Nothing of the runtime crosses the boundary, but the sentence overstates the separation.

For engineers

client-org-mock impersonates the IT infrastructure of a customer organisation: an OpenID provider, a SAML identity provider, a directory-provisioning client, a security-event sink and a webhook receiver. All five mount under path prefixes on one port, so one instance is one origin, and a fleet runs one instance per tenant with its own recording database. It is the passive half of the pair: the systems an application calls out to.

The problem it solves

Every enterprise integration is a claim about what happens on the other side of a boundary you do not control. Signature validation, per-tenant routing, provisioning, security-event delivery and webhook signing all fail in ways that look identical from inside the application: a request was sent, no error was raised, and nobody knows whether the right thing arrived at the right place.

Isolation defects are worse still, because the symptom is invisible from a single tenant. One customer’s audit records arriving at another customer’s security sink produces no error anywhere; the sending tenant sees a success and the receiving tenant sees data it should never have had. That class can only be caught by watching two independent receivers at once and asserting that one of them stayed silent, which is precisely what this double makes possible.

What it does

Each face wraps a standard library rather than reimplementing a protocol, mirroring the framework’s own choice so the handshake is symmetric. The package owns the wiring and the recording and nothing else: no fake business objects, only a small seed so sign-on and provisioning can round-trip.

Every observation is written to a durable per-instance database, carrying the face, a sub-kind, a one-line summary and an optional idempotency key mirroring the application’s own de-duplication. A scenario reads them back over an inspection surface, which is what turns “did the assertion land” into a row count rather than a guess. Because the database is per instance, the isolation question is answered without any shared query surface: the tenant that should have received the traffic has rows and every other tenant has none.

The package sits deliberately outside the framework’s workspace, with its own lockfile, so its dependencies never touch the framework’s resolution. The one exception is the security-event receiver, whose parser is written from the published grammars rather than from the framework’s emitter — and that independence is the entire point: a receiver derived from the producer would agree with the producer by construction, and a format defect would read as agreement.

The directory face inverts the direction. Wildo is the provisioning SERVER there, so the double is the client that pushes users in.

Dependency-free end-to-end spine Tool

The pieces every test lane needs, from running a scenario to surviving a backend restart, live in one package with no third-party dependencies, so packages that must stay isolated can still share them.

One scenario engine drives every end-to-end lane: a step triggers a real capability, observes the outcome on one or more channels, optionally extracts a value later steps read, and asserts what the application’s own store says.

Limits

It cannot contain anything that needs a dependency, and that boundary is enforced by the fact that it has none. The browser-backed surface therefore lives in its own package, and every concrete surface implementation lives with its lane.

It defines the surface contract and the isolation assertion; it does not know what a Wildo resource, role or organisation is. Everything domain-shaped is on the far side of the adapter.

The log observer parses one record per line, so a stack running its logs in human-readable mode yields nothing parseable to it — which is why the fatal gate in the harness reads raw lines instead of reusing this parser.

For engineers

@wildo-ai/testing-core holds the parts every test lane needs and none of the parts any one lane is about: the scenario engine, the surface and adapter contracts, the isolation assertion, backend-flap resilience, the log observer and the managed child process. It declares no runtime dependency at all, and it is exported as TypeScript source rather than as a build, which is what lets a package with its own lockfile consume it without inheriting anything.

The problem it solves

Test doubles have to be independent to be worth anything. A double that impersonates a customer’s identity provider is only evidence if it speaks the protocol on its own terms rather than borrowing the types of the thing it is testing, and a double that shares a lockfile with the engine cannot demonstrate that it resolved a signature the way an outsider would.

Independence usually costs duplication. Each isolated package ends up with its own copy of the scenario loop, its own retry, its own idea of what an assertion is, and the copies drift until the same failure reads differently in two lanes. This package is the way out: the parts that are genuinely common carry no dependencies, so importing them costs an isolated package none of its isolation.

What it does

Cross-scope isolation is not a separate mechanism. It is a flag on an assertion, asserting that the active scope recorded the expected traffic AND every other scope stayed silent. That detects misrouting from record counts alone, with no payload parsing — which is why it works identically over an identity provider, a webhook receiver and a security-event sink.

The whole engine is generic, so a surface brings its own kinds rather than the engine knowing about any of them. That is what makes one loop drive an HTTP API, a browser, a message queue, a backend log and an external double.

One seam injects the application. An application supplies provisioning, capability configuration, a trigger, a store read and its addresses; the subprocess form turns that into a cross-process contract — so the adapter runs in the application’s own workspace with the application’s own module resolution, while the scenario stays application-agnostic.

The resilience module exists because a development stack restarts under recompile churn. Rather than widening timeouts, every application-facing call gates on the health endpoint and retries within a readiness ceiling — and a transport failure is described AS one, so a caller can tell an absent backend from a wrong answer.

Engine behaviour end-to-end harness Tool

A registry of named scenarios drives a real running application over real HTTP and a real browser, and fails the run if the backend logged anything fatal while they ran.

Fifty registered scenarios drive a running stack the way an outside system would, and one command is the bar.

What you decide

Adding a scenario is a script and one registry row. The harness supplies the adapter, the attach, the surface, provisioning, authentication and teardown — so an ordinary API scenario is just the pipeline of steps.

Limits

The gated command with no arguments does not run everything registered. The plan intersects the registry with what the application’s own adapter declares. The difference is a subset by DECISION rather than by drift: each of the six left out carries a written reason — an equivalent lane already gates the same contract, a real external fleet or model budget is spent, or the surface is one most changes do not touch.

Two scripts sit beside the registry with no row, and both are deliberate: one is a superseded proof kept as a runnable historical record, the other a stack-independent self-test of the harness’s own plumbing. Neither runner can reach an unregistered script, so both run only if someone invokes the file directly — which is what they are for.

One application implements the adapter. The seam is built for more and is exercised by one, so “works across applications” is a property of the design rather than a measured result.

The suite attaches to a stack; it does not diagnose one.

For engineers

@wildo-ai/engine-behavior-e2e is the suite that answers “does the engine actually work”. Fifty named scenarios are registered in one file; each is a script that provisions its own organisations against a running application, drives one engine capability over real HTTP or a real browser, reads the result back from the other side of a process boundary, and tears down. A run is green only when every assertion passed and the backend logged nothing fatal while they ran.

The problem it solves

Most of what this framework claims is about behaviour under conditions a unit test cannot create: two tenants at once, a signed assertion arriving from outside, a job that has to survive a broker, a token minted for one surface being refused on another. A test that mocks the boundary proves that the mock behaves; it says nothing about the running system.

The second problem is subtler and cost more. A suite can pass every assertion it makes while the application under it is failing at something the suite never looked at, so the report is green and the product is broken. The harness treats that as the default hazard rather than an edge case: the run window is watched independently of the assertions, and a run in which the backend screamed is not a passing run no matter what the scenarios concluded.

What it does

A scenario is a row carrying a stable identifier, the script that replays it, the lane it asserts against, and the runtime surfaces it needs ready. Forty-seven sit on the application-runtime lane and three on the control-plane lane. A third lane is declared and deliberately unused, so the tag is honest about being one of several on one substrate rather than pretending the substrate is single-purpose.

Everything application-specific sits behind ONE seam — an adapter shipped inside the application, injected as a subprocess whose working directory and command resolve from environment bindings rather than from a hardcoded path. A scenario therefore names capabilities, never the application, and a second application slots in by shipping its own adapter.

The gated command attaches to the stack a developer is already running, gates on health, pins the current end of the development log, runs the selected scenarios, then scans only what was appended during the window. The gate matches the fatal token on the RAW line, in both log shapes, because a parser that reads only structured records would certify a human-readable run as clean. It also matches criticals a caller caught by contract and logged at warning level — which is where a fire-and-forget dispatcher hides its own breakage.

Because every scenario opens with a destructive pre-clean keyed on a deterministic reference, two runs against one stack would delete each other’s fixtures mid-drive. A second run is refused by name, and the claim is held by the process TREE so a runner’s own subprocesses inherit it. The marker is honoured only while the owning process is alive and under two hours old, so a hard-killed run cannot wedge the lane.

External-system provider simulators Tool

Standalone doubles for the business systems an application reads data out of, so a data pipeline or a provider operation can be exercised against a real socket without a real business system.

Protocol-faithful doubles for the external systems an application reads from — a business suite’s remote-procedure envelope, two versions of a standard query protocol, and a route-driven generic REST face.

Limits

No scenario in the end-to-end registry drives it, and nothing outside the package references it. Each face carries its own unit tests and has been exercised directly, and the claim that an application’s data pipeline works end to end against one of them has not been made by a lane.

The doubles are faithful to a scoped subset of each protocol, chosen as what a query compiler realistically emits. Constructs outside that subset are not implemented, and the source says so at each face.

They carry no business logic and no persistence. A fixture is supplied at start-up and read back; nothing writes.

For engineers

provider-simulators stands in for the external target systems an application reads from. Four faces are implemented: a business-suite remote-procedure endpoint, an OData version-four endpoint, a version-two endpoint in the flavour a large enterprise suite actually publishes, and a route-driven generic HTTP double for provider operations. Each is a standalone server started from one orchestrator, with no framework imports.

The problem it solves

Reading data out of somebody else’s system is mostly a question of dialect. The envelope differs, the paging property differs, the query language differs, and a wrong answer looks like an empty result rather than an error. Testing that against the real system means holding an account, a network path and a data set, none of which belongs in a test lane; testing it against a stub written from the same assumptions as the reader proves only that the assumptions are self-consistent.

The version-two case is the clearest illustration. The engine’s OData reader expects a value array and a next link, which is version four. A widely used enterprise business-partner service publishes version two, whose envelope wraps everything in a different property, names its results differently and carries a different next link and count. A version-four reader pointed at it finds no array and fails on the first page. Only a double that is faithful to the published version-two format shows that, which is why the two are separate doubles rather than one with a flag.

What it does

Each face is faithful to a PUBLISHED protocol rather than to the framework, and none of them imports anything from it. That is the load-bearing property: a double derived from the reader would agree with the reader by construction, so a framework defect could never surface.

The business-suite face implements the envelope, the authenticate call including its rejection answer, and the read family with the domain query language, its prefix-notation combinators and its operator set. The newer query face parses the filter grammar subset a query compiler realistically emits, by recursive descent, and answers the metadata document as well as the count. The older face implements the other envelope, the other paging and the other count.

The generic double is deliberately a different shape. A provider operation has no dialect — only a method, a path template, parameters and a body encoding — so this face is route-driven: a test declares routes the way a vendor’s API reads on paper, and the double records what actually ARRIVED, including query parameters, headers and the raw body with its content type. That record is the assertion surface, and it is what turns “the parameter went to the query rather than the body” into a checkable fact rather than an inference from a successful status.

Two faces carry a knob that forces one throttled answer after a chosen number of calls, so transport-retry machinery has a live counterpart rather than a mocked one.

Platform control-plane end-to-end runner Tool

The platform services that manage applications are tested from the host as external systems, on the same substrate the application lanes use and with a fatal-log gate scoped to the platform's own output.

A separate end-to-end lane for the control plane, built around the fact that the control plane is not an application: no provisioning, no tenant, no adapter, and one observation scope.

Limits

The three platform scenarios are on a separate axis from the application matrix and appear in no application’s declared list, so the application command never runs them.

The recovery journey is destructive by design: it wipes every local backing service’s data. Gated behind an explicit flag and meant for a disposable runner, never for a developer’s working stack.

The package has no local container-first workflow and no in-cluster lane; both are stated as non-goals rather than as gaps to be filled later.

The contract lane is a placeholder that skips TRUTHFULLY when no executable contract suite exists — a deliberate choice over a lane that reports green having run nothing.

For engineers

@wildo-ai/platform-e2e-runner provides the control-plane half of the end-to-end substrate: the back-office API surface, the three principals a request can arrive as, the shared verdict for a service-token read, and the assertions built on them. Three scenarios in the shared registry use it, and the package also carries its own browser and API lanes plus a deliberately opt-in destructive recovery journey.

The problem it solves

The platform services are what manage applications: they hold each application’s configuration, issue its credentials and register its scheduled work. An application’s own tests cannot cover them, because from an application’s point of view the control plane is simply somewhere its configuration comes from. Nothing else would look at them at all.

They also fail in a shape that ordinary assertions miss. A control plane that manages secrets can answer a configuration read successfully while logging a fatal error resolving a managed-secret branch, so a successful status is not evidence that the read was correct. And a key generation can drift, where the stored verification key and the materialised signing key stop matching, which presents as an authentication refusal that reads like a configuration mistake and is really a broken initialisation.

What it does

Its surface drives the back-office API and returns the status and body for ANY status — so a refusal is data the caller classifies rather than a thrown error.

Three principals are supported, matching the three doors the control plane actually opens: an application’s own platform credential, which is exactly what a real backend sends; an administrative credential; and a service token. A call can override the default, so one scenario can prove that a door which should be shut is shut.

The service-token verdict lives in ONE place. Every control plane classifies the same way — served, key generations incoherent, or an unexpected fault — and only the human-readable message differs per door, so each door supplies its wording and the classification is written once.

The gated entry point reuses the registry, the replay command and the fatal-gate wrapper from the application lane, and changes only the gate’s SCOPE. The development command tees the platform tree and the application tree into one log with per-line labels, so the platform gate reads only the platform lines: an application’s fatal error never reds a platform run and a platform fatal never reds an application run.

One of its contract lanes checks the customer-infrastructure double against wire drift — which is how an independent double stays independent without silently diverging.

Shared browser drive with a gated login Guarantee

Browser scenarios share one implementation of signing in, and a repository check refuses any browser wait that neither gates on the backend being up nor says in writing why it does not need to.

The login every browser scenario performs is defined once — so there is no ungated path left to author for those steps.

Limits

One wait is deliberately not shared. Asserting that the authenticated shell has painted looks duplicated and is not: the password scenarios wait on a client render after an already-gated navigation, while the single-sign-on scenario has no preceding gate and its one wait absorbs the entire return leg, two backend round trips. Same locator, materially different dependency.

One scenario keeps a private copy of the second-factor drive on purpose, because its subject is the challenge screen itself rather than passing through it — there, the waits ARE the assertions.

The gate does not rescue a step that fails while a restart lands in the middle of it. The step still fails; it just fails saying the right thing.

The check is lexical rather than a full parse, over a tokeniser that tracks strings, templates and comments, covering a fixed list of wait calls. Its search roots are named in the file — if browser scenarios ever move outside them, it would inspect nothing and report success, which is why the file says so at its own failure message.

For engineers

Every browser scenario signs in through one implementation, and that implementation gates each wait that cannot succeed while the backend is away. A repository check enforces the same rule on waits a scenario writes for itself: a browser wait is either inside the gate or carries a comment saying why it does not need to be, and anything else fails the check.

The problem it solves

A browser wait absorbs a slow backend; it does not absorb an absent one. A development stack restarts under compile churn, and when it does, a wait for a password field expires with a message naming a locator. That message is indistinguishable from a genuinely broken form, and it was reported as a product failure. The investigation cost more than the outage.

Widening the timeout does not fix it, and that was measured rather than assumed. Outages were timed at sixty-eight seconds, about a hundred, and two hundred and seventeen. The distribution is long-tailed because recompiles stack, so any fixed number is eventually walked through. Gating costs nothing when the stack is up and absorbs the whole outage when it is not.

The deeper problem is that this rule was already written down, already understood, and applied to one of four scenario files. The other three each carried their own copy of the login, one of them waiting on the identical locator on the identical form, because the incident named one scenario and nobody asked which other files contained the same wait.

What it does

It owns the wait for the form to paint, the two-phase login where an address is submitted and the form then swaps to a password method, the reload that returns a fresh unauthenticated form, and the second-factor variant. Where the application lands afterwards is left to the scenario, because that is the scenario’s subject.

The gate waits for health within the readiness ceiling, runs the step, and then does the one thing that makes the whole mechanism worth having: if the step failed AND the backend is not answering, it raises an error naming the infrastructure while preserving the original as its cause. If the backend IS answering, the original error is rethrown completely untouched — because then it is a real product failure and must read as one.

It deliberately does not retry. An adapter subcommand is replayable and a browser step is not: re-running a click that already created a row would corrupt the scenario’s own state and could manufacture a pass. The gate is side-effect-free in both directions.

What the shared drive cannot cover is covered by a check. It scans every file that imports the browser surface, finds each wait, and requires it to be either inside the gate or carrying an explicit declaration with a reason. Files are discovered by IMPORT rather than by filename, so a browser scenario named anything at all is covered the day it is written. The check does not decide which waits need the gate; it refuses to let the answer stay implicit — the guarantee that was actually available.

The declaration is a decision rather than a suppression, and the distinction earns its keep: a pure client render after an already-gated navigation genuinely should not be gated, and reflexively gating everything would blur which waits depend on the backend at all.

Third-party integrator test double Tool

A standalone service that behaves like an external integration consuming your application's API, so the outward-facing surface is proven from the outside rather than from inside the process that serves it.

An outside integrator, driven as a real client: it authenticates the three ways an application actually offers, calls the agent surfaces, and receives the outbound webhooks.

Limits

It has no business logic of its own. It proves that an outside caller reaches, or is refused by, the application’s surface; what the application then stores is asserted through the application’s own adapter.

Both model-driven legs run real models on purpose, so those scenarios need credentials and cost money — which is why they sit outside the deterministic lane families and why credit exhaustion is a distinct outcome.

The tool-protocol client has no instance selector, because the command contract is frozen — so it always drives the default server. Tools curated onto named servers are outside what it can reach.

Its own status notes describe the build in phases, some of which predate later work. Read the source for what a face does today; the status prose is a record of how it arrived.

For engineers

client-integration-app is the active half of the pair: where the customer-infrastructure double receives what an application sends, this one authenticates and drives. It holds an authentication face, a role-checked API client, an agent-protocol client, a model-context-protocol agent driven by a real language model, and a webhook receiver of its own. It reaches the application over HTTP only, holds no literal secrets, and takes its credentials from the scenario at bind time.

The problem it solves

An application’s outward-facing surface is the one part of it that no in-process test can honestly exercise. Authentication, audience binding, role checks, tenant scoping and tool exposure all behave differently to a caller that shares the process and its types than to one that does not, and the differences are exactly where the interesting failures are: a token minted for one surface accepted on another, a tool that advertises one contract and enforces a second, a webhook signed with a key nobody validated.

There is a second reason to build the caller rather than script the calls. When the surface is an agent protocol, the realistic consumer is a language model choosing tools from a catalogue it just discovered, and what it chooses is not what a hand-written script would send. A double that discovers and drives the way a real integrator does is the only way to find out whether the catalogue is usable.

What it does

One frozen contract crosses the boundary. The double runs as a spawned subprocess exposing a command endpoint; the scenario posts a command and reads back an observation. The shapes were frozen after the first real path was built rather than sketched in advance, and later faces extended them additively.

Authentication covers all three methods: machine credentials with discovery, a delegated authorisation-code exchange with a proof key where the audience is required, and an API key echoed as a raw secret. Tokens are cached per principal and the header is resolved per method, so a scenario asks for a PRINCIPAL rather than for a mechanism.

The tool-protocol face is a real agent. It discovers the catalogue and drives real work through it, and reports its tool trace so a scenario can assert what the model actually called. Because a real model can also run out of credit, that outcome is reported as INCONCLUSIVE rather than as a failure: a lane whose skips are indistinguishable from failures teaches everyone to ignore it.

The webhook receiver is a second server inside the same process. It verifies the signature against the application’s own published key, fetched at run time from the administrative read rather than pinned in the double, and records what it received on the same inspection shape the other double uses — so the harness orchestrates both the same way.

Build and repository checks

How the framework compiles, publishes and polices itself.

refuse driftrefuse drift

Source

Compile

Publish

Checkers

An application installs it

How the framework compiles, publishes and polices itself.

Repository checks and diagnostics

Code-conduct checkers Tool

Rules that no type system can express are enforced by dedicated checks, each of which can prove it is not broken.

A family of small checks that read the working tree directly — no build, no install — and refuse to let a decision stay implicit.

Limits

Most are advisory about intent and strict only about visibility. A check that reports a site is saying the site has not declared what it is, not that it is wrong.

Two of the thirty-six carry no self-test, so their discovery is unverified. One is reachable from neither a named command nor a pipeline, so nothing runs it on a change.

They do not all gate. Roughly a third are reachable only by running them deliberately.

For engineers

Some of the rules a framework depends on cannot be written as types. An end-to-end assertion must reach the database through the adapter-neutral seam or say out loud that one dialect is its subject. A package subpath must be the only door onto its surface. A closed vocabulary must have one named home. Each of those has a dedicated script under code-conduct, thirty-six of them, and almost all of them ship a self-test that plants each failure shape and asserts it is caught.

The problem it solves

The rules that matter most in a framework are usually the ones a compiler cannot see. They are properties of how code is arranged rather than of what it evaluates to: which package a symbol is reachable through, whether a string is a vocabulary or a wire value, whether a security-relevant action emits a record. A type system has no opinion on any of them, so the fallback is review, and review is what authoring speed outruns. One of these checkers was written after a measurement that makes the point exactly: around a hundred call sites had been converted to a store-neutral seam, and by the time the conversion was reviewed, ten new sites of the old kind had arrived in code written during it. A sweep fixes the population that exists today; the population refills.

There is a second, sharper reason these are scripts rather than conventions. A convention is enforced by whoever remembers it, and nobody remembers thirty-six of them.

What it does

What most of them deliberately do NOT do is decide what is correct. A check cannot tell a deliberate exception from an unconverted one, so the guarantee on offer is weaker and honest: it refuses to let the answer stay unstated. A site that genuinely needs the exception carries a marker naming its reason, in a comment beside the code — visible in review, surviving a file move, and unable to drift from what it explains.

They are not text matching where text matching would be wrong in both directions. One check runs a real tokeniser, because its own source discusses the forbidden call in prose that must not be counted, and because the target appears inside string templates that must not be either. That was learned the expensive way: the first live run reported twenty-six sites where a plain search found sixty-one, because a pattern containing a quotation mark opened a string that swallowed the rest of one file — and every short fixture had passed.

Why a check proves it is not broken

This answers a failure with no symptom. A check reports findings; when it reports none, that reads as a clean repository — and there is nothing in the output to distinguish that from a check whose discovery has silently stopped matching anything. A widened directory layout, a renamed extension, a tokeniser that lost half the file: both print the same thing. So a broken check is not merely useless, it is worse than absent, because its silence is taken as evidence.

The answer is that a check carries fixtures of both kinds and asserts both directions: each planted bad input must be reported, and each good input must not. The second half is what makes it a test rather than a demonstration — detection without a clean control proves only that something fires, not that it discriminates. Several go further and check themselves against the live tree, so a tokeniser regression that stops seeing a file becomes a red run naming that file.

Shrink-only baselines, and what a check should refuse

A baseline is a different design decision from a gate, and the two answer different questions about a rule that is right and a codebase that does not yet satisfy it.

A gate refuses the state outright. That is correct for a rule with no pre-existing population.

A baseline is for the other case: the rule is correct, the population predates it, and converting everything before the rule can be enforced means the rule is not enforced for as long as the conversion takes — which is when the population grows. So a baseline records what exists as a per-file ceiling and enforces one thing only: that the ceiling never rises. Converting a site lowers the count, the row is deleted at zero, and the self-test refuses a row naming a file with nothing left to convert, so the ledger cannot rot into a list of resolved entries.

The rule the baselines carry in their own text is what keeps this from becoming an allowlist: never raise a count to silence a new finding. A new occurrence is the defect the check exists to catch, and the answer is to fix it or to declare it at the site with a marker naming the reason. A marker is visible in review; a raised number is not. The steady state of every one of these files is empty.

Dogfood diagnostic commands Tool

One screen says whether the reference application's development environment is coherent, and a second streams every one of its process logs together.

Two commands answer the question that costs the most time in a development stack: is what I am running actually current?

What you decide

Both are gated to a framework checkout and never appear to someone running the command line inside their own application. The currency sweep is also a plain script invocation, deliberately: the operator who needs it is usually mid-incident with a command line whose own compiled output is one of the suspects.

Limits

Both commands are hardwired to one reference application. The paths they read are that application’s own, so they say nothing about any other application in the repository.

Nothing here fails a build or a boot. The sweep exits zero even with findings by default, on the stated ground that a currency check that failed a start would be a new way to break the stack — a strict flag exists for a pipeline that has decided otherwise. Acting on a finding is a separate, manual step.

The sweep reports staleness, not correctness. It compares timestamps and file sets, so an artifact rebuilt from wrong source is current and reported as such.

For engineers

Two commands answer the question that costs the most time when a development stack misbehaves: is what I am running actually current. wildo fwk wt-status prints one screen covering build freshness, linked-snapshot coherence, registry alignment, process and port state, and index freshness. wildo fwk wt-tail streams every process log of the same application together with coloured prefixes. Both are read-only.

The problem it solves

In a repository where an application consumes the framework through linked copies of compiled output, a large share of apparent bugs are not bugs. A symptom that reproduces in one process and not another is usually a stale compiled artifact, a linked snapshot that has fallen behind, or a process that has been running since before the fix. Every one of those presents as a logic defect: a missing export reads as a bad import, a stored document rejected by a schema reads as a validation bug, a service that will not start reads as a configuration problem. The investigation goes into the code, and the code is fine.

What makes this expensive is that the cheap check is never the one anyone runs first, because at the moment of the symptom there is no reason to suspect the artifact. These commands exist to make that check cost one line instead of an afternoon, and to make it a single screen rather than six separate questions.

What it does

The snapshot compares each package’s compiled output against its source, then validates the linked snapshot the application resolves its framework dependencies through — reporting whether files are missing, drifted, or present in the snapshot after being DELETED from the framework. It compares the three module registries an application declares, which have to agree and are edited separately. It reports which processes are up, what their last build signal says, which ports are occupied, and whether the code-intelligence index is fresh.

Each finding names the exact command that repairs it, and the repairs differ: a drifted file is reconciled, a file left behind by a deletion has to be pruned instead, and an unfinalized compiled tree is a build problem wearing a snapshot symptom.

The currency sweep behind the same question is broader and application-agnostic. It asks one thing across every derived surface: whether the file watchers can still see edits at all, compiled output against source, unfinalized emit, accepted generations against the paths they name, linked snapshots compared by file set, the package store against the links that reach it, the configuration cache against its inputs, the provider set each runtime will bind against the configuration that declares it, each supervised process’s START time against the build it loads, and published documentation. It discovers application roots rather than being told them, and it prints both timestamps and the delta so a reader can see which side of the threshold a finding sits on.

The log tail is the companion to that: the development stack does not centralise its logs, so it finds whatever log files exist, prefixes each line with a coloured label, and can list which logs are present and which are missing rather than silently tailing nothing.

Symbol-accurate code intelligence Tool

A queryable index of every symbol in the repository, so the real consumers of a change can be found across package boundaries in under a second.

A symbol index over the repository’s source, so “who calls this” is a query rather than a text search that crosses package boundaries wrongly.

Limits

Building the index is expensive — a cold build was measured at roughly twelve and a half minutes. That is the reason for the daemon, and the reason a stale index is a real possibility rather than a theoretical one.

Both tools are installed non-fatally by the framework installer, so a developer whose install failed has no index and gets no error until they try to query it. The index tool has releases only for the platforms the installer selects, so elsewhere the whole capability is absent — and the installer says so and continues.

Neither the index nor the query path is part of a generated application. This is repository tooling for people and agents working on the framework.

For engineers

A code-intelligence index of the whole repository is built into a binary artifact and converted into a queryable database, so a question like “what actually uses this type” is a sub-second query rather than a text search. The distinction that matters is package boundaries: a text search finds occurrences of a name, and an index finds references to a symbol, which is what a change across a package boundary needs.

The problem it solves

At a million lines and thirty-odd interlinked packages, the cost of a change is dominated by enumeration. Before renaming a type, reshaping a schema or moving a symbol between public entrypoints, you have to know every consumer, and getting that list wrong produces a regression that compiles.

Text search is the tool everyone reaches for and it fails in both directions here. It matches names that happen to coincide and misses references that resolve through a re-export, an alias or a published declaration. It is also quietly blind: the repository’s default search tool skips hidden directories, and one of the largest consumer trees in the repository lives under a dotted directory. An enumeration run that way returned fifteen files where the real number was thirty-five, and the list looked complete, which is the dangerous property.

What it does

An index is produced and converted into a queryable database, so a lookup is a query rather than a scan. It is safe to run alongside the compile watchers.

Concurrent runs are serialised by an atomic directory-creation lock — chosen because it needs no external tool and works on every platform the repository is developed on. That choice was made after the previous approach, guarded by a check for a tool that does not exist on one of those platforms, silently skipped the guard entirely: over two days the watcher logged ninety-four index starts, thirty-two completions and no skips at all, and the overlapping runs corrupted each other’s output while the reported state kept moving.

The lock distinguishes a live owner from a dead one and from a recycled process, and only breaks a lock once it is old enough that it cannot belong to a run still starting. Its self-test exercises each of those independently, neutralising the other check in each case, so a passing run can only be explained by the check it names.

A daemon watches sources and regenerates on save with a delay, so the index settles after activity rather than rebuilding on every keystroke. It can run in the foreground, in the background with a log, or start at login, and it reports its own state.

A routing document sits beside the tooling and decides which tool answers which question, because the index is not the right answer to all of them: a literal string in a comment is a text search, a structural pattern is a structural matcher, and an architectural dependency rule belongs in a dedicated check. One command wraps a symbol query with a classification of what the change crosses, so the answer arrives with the rules a developer should read before editing.

Generated assets, schema and dependencies

Database schema planning and migration Tool

Changes to a relational database are planned, compared against a committed baseline, generated as migrations and applied in order, from the command line.

For a relational application, the physical schema is planned from the model, the difference is reported, and a migration is written from that difference — with the plan and the migration advancing as one change.

What you decide
wildo db diff
wildo db generate --name <label>
wildo db migrate

Migrations are committed folders beside the plan they advance.

Limits

This is the relational path. An application on the document store does not use it.

Several things are refused rather than automated, each naming its remedy. A migration whose file has changed after being applied is refused, because the repository and the database then disagree about history; re-accepting the current bytes is a deliberate command. A statement that drops a table or a column is refused unless the file carries an acknowledgement — a reviewed artifact in the migration rather than a flag on the command. Index creation outside a transaction is refused outright, because supporting it would cost the whole-rollback property everything else depends on.

The reverse case is tolerated on purpose: a deployment shipping fewer migrations than the ledger records is a rollback, and refusing it would break the recovery a fleet depends on.

There is no automatic reversal. Undoing a migration means writing the migration that undoes it.

For engineers

A Wildo application declares its data as decorated schemas, and on a relational database those declarations have to become physical tables and columns. The wildo db commands make that a reviewable sequence: compare the current model against a committed baseline, generate a migration draft from the difference, apply pending migrations in order, and correct the ledger when a human has intervened.

The problem it solves

When the shape of a database is derived from application code, the temptation is to let the application reconcile the database at start-up. That works until the first change that cannot be inferred safely. Dropping a column and renaming one look identical from the outside; a column that gains a constraint needs the existing rows to satisfy it first; and a fleet of instances starting together will each try to reconcile the same database at the same time.

The other half of the problem is review. A schema change is one of the few changes whose worst case is unrecoverable, and it is exactly the kind of change that is hard to see in a code diff, because what changed was a decorator on a field. Turning it into a generated file that is committed, read and approved makes the destructive part visible before it runs rather than after.

What it does

The baseline is a committed file describing the plan the application’s model implies. Asking for the difference recomputes that plan from the live model and reports what separates the two, each change classified as safe, destructive, or requiring a data migration. A check mode exits non-zero on any drift — the ratchet: it does not decide what is correct, it refuses to let the answer stay implicit, because an unenforced snapshot rots.

The model is computed in a process spawned inside the application’s own workspace rather than imported into the command line. That is deliberate: the model is the application’s own modules merged with the framework core, resolved through the application’s own dependencies — and importing it here would bind the application to the command line’s framework version and to its schema library’s decorator state. The comparison then happens in the command line, because comparing two plans is a pure step.

The migration runner carries the guarantees. Its state lives in a table inside the database being migrated, deliberately not modelled as a resource, because it has to be readable before the resource system boots and must be unreachable from the API. Exclusion is a session-scoped lock in that same database, so the lock lives in the same failure domain as the writes it guards and releases itself when its holder dies, rather than relying on an external expiry that can lapse mid-migration. Instances that do not win the lock wait and then proceed, and every instance runs the schema verification afterwards regardless — so a runner defect cannot silently become a served schema.

Each migration runs in its own transaction. Because schema statements are transactional here, a failed migration rolls back whole: the database lands exactly at the previous migration, the ledger records the failure with its error, and recovery is to fix the draft and run again rather than to reconstruct a half-applied state.

Dependency alignment for applications Tool

One command brings a standalone application's dependency versions and declared peers back into step with the framework release it has installed.

An application aligns its dependency declarations to the framework release it actually installed — the pins the framework tested against, and the peers each framework package expects a consumer to supply.

What you decide
wildo align-deps

Read-only by default, exiting non-zero on drift. The upgrade order matters and the command states it: bump the framework versions, install, align, install again — the new pin set can only be read once the new framework version is on disk.

Limits

It never changes a framework version. Which release to adopt is the operator’s decision, and everything else follows mechanically from it.

It never removes a name. A managed name the closure does not require may still be the application’s own dependency — and an early version that pruned surplus entries stripped real dependencies out of two packages.

It writes declarations only. It does not install, so the resolution is unchanged until the next install, and the peer half specifically needs that second install to take effect.

A freshly scaffolded application legitimately needs one alignment run after its first install, because scaffolding writes pins from the framework checkout while pinning the framework itself to the published release — and those disagree whenever the checkout is ahead of the last release.

For engineers

wildo align-deps reads the framework packages an application actually has installed, derives from them the third-party versions the application should pin and the peer dependencies each of its packages must declare, and reports or writes the difference. It is what an application runs after moving to a new framework release, and it needs no framework checkout to do it.

The problem it solves

When an application is scaffolded, the versions it pins and the peers it declares are computed from the framework at that moment. Afterwards nothing recomputes them. The application moves to a newer framework release, keeps the old third-party versions, and quietly runs a set of libraries the new engine was never tested against.

The peer half is worse, because it cannot be repaired by reinstalling. A package manager override rewrites a version some manifest wrote down; it never creates one. So a peer dependency that no manifest declares is resolved automatically, that resolution is recorded, and it is then never re-derived: the same install command, repeatedly, changes nothing. The visible symptom arrives later, when a version range narrows and a resolution frozen months earlier starts reading as a live conflict, at which point the code looks like the culprit and is not.

What it does

Everything is derived from the framework packages resolved in the application’s own tree. Nothing new has to be published for that to work: the publish lane already substitutes the framework’s single root pin into every published manifest — exact for ordinary dependencies, widened for peers — so the pin set and the peer closure are recoverable from the installed packages themselves. That is why it reads the installed tree rather than a published list: the data cannot drift from the packages it describes, because it IS them.

Findings split on two axes rather than being degrees of one thing: whether a name belongs in the application’s own pins or in a package’s dependency list, and whether it is absent or present and wrong. The one worth naming is a peer declared at a concrete version rather than as a wildcard — because the framework’s pin then cannot reach it, and a later version bump silently will not land.

Exclusions are the application’s own, in a file seeded when the application is scaffolded. That is the right owner: the application knows which names its own toolchain controls, and it is the party that breaks when the judgement is wrong.

A scenario that creates a new workspace package inside an application reads a delivered copy of the peer closure, so a site, a portal or a background worker is born with the peers it needs declared rather than with none.

Design-token and brand tooling Tool

The application's visual design is written as configuration, generated into the stylesheet every surface reads, and its brand assets are pushed to each site by one command.

Two commands turn declared design decisions into the files the surfaces actually read: the design system into stylesheet variables, and the accepted brand assets out to every surface that serves them.

What you decide
wildo design-tokens generate
wildo brand propagate

with a dry run that prints the whole plan, and a flag to run one destination.

Limits

The token generator writes one region in one stylesheet per surface. It does not distribute the design system to the other surfaces itself; each surface reads the tokens from the generated block in its own file.

Brand propagation reaches five destinations today — the application’s public assets, the marketing site’s public assets, the site’s social-preview images, the documentation site’s static assets, and the backend’s runtime configuration. An email destination and a structured-data destination are named in the command’s own notes as absent, and neither is implemented.

Neither command validates the result visually. A design system that parses and generates can still produce an unreadable contrast ratio.

For engineers

An application declares its design system as a configuration file, and wildo design-tokens generate turns it into the custom-property block every frontend surface reads. A separate command pushes the application’s accepted brand assets to each site that shows them. Both write into files a developer also edits, so both write into a marked region rather than owning the whole file.

The problem it solves

Colours, spacing, radii and typography end up duplicated across a product’s surfaces: the application, the marketing site, the documentation portal, and the emails. Each copy is edited separately, so within a few months they disagree, and the disagreement is the kind nobody files a bug about because each surface looks fine on its own.

Generating them from one declaration would be the obvious answer if not for one thing: the stylesheet is not only generated content. A developer has real hand-written CSS in the same file, and a generator that owns the file destroys it. The same is true of brand assets, which land in several served directories and in the head of several sites, and which may have been supplied by a person rather than produced by a generator.

What it does

The design system is authored at a fixed path. Generating loads it, produces the custom-property declarations, and replaces the content between a start and an end marker in the existing stylesheet, leaving everything outside the markers untouched. A separate step inserts that marked region into a stylesheet that does not yet have one, and another checks the authored configuration. The generated region carries its own notice saying it is generated and naming the command that regenerates it.

Brand propagation reads the COMMITTED source of truth for the application’s resolved assets, never a staging directory, and runs every destination it discovers. The destinations are found by file rather than enumerated in the command, so a new surface plugs in by adding one file — demonstrated rather than promised: the destination that stamps the assets into the backend’s runtime configuration was described as a future addition and was picked up without any edit to the command.

Each destination copies the asset files into one surface’s served directory and reconciles that surface’s references to them. Because it only ever reads the committed assets, it runs identically whether they were generated or supplied by hand, and it is a clean no-op when there are none.

OpenAPI generation for an application's API Tool

A complete, browsable API reference is generated from the application's own resource declarations, with operation names a developer would have chosen by hand.

The application’s API description is generated from what the application declares, and committed — reviewable in a diff and servable with no generation step.

Limits

It describes the API the application declares. An endpoint added outside the resource system is outside the projection and therefore outside the document.

The conservation check is a consumer-side comparison between the rendered navigation and the generated documents, so it proves the reference represents every generated operation once. It does not compare either against a running server.

The generator produces the document; serialising it to either format is a separate step — which is why the same document appears twice on disk rather than once.

For engineers

An application’s HTTP API is not written by hand, so its reference is not either. Each operation the application exposes is projected into a validated description, and a generator turns those into OpenAPI documents: one for the public API, one for the administration API, each serialised both ways. The output is meant to read like a reference a developer wrote, not like a dump.

The problem it solves

Generated API documentation has a reputation, and it is deserved. The usual output is technically complete and unusable: operations named after internal handlers, every request body inlined so the same shape appears forty times under forty names, authentication described nowhere, error responses absent, and defaults captured from whatever the machine that generated it happened to hold. A developer reading it cannot tell which of six similar endpoints they want, and a generated client built from it has method names nobody would type.

The alternative, writing the reference by hand, fails differently. It is correct on the day it is written and then diverges from the API silently, because nothing compares the two.

What it does

The projection comes first: each exposed operation becomes a description carrying its resource, its variant, its address, its authentication mode and its schemas, and that projection is validated before the generator sees it, so every step downstream can assume a well-formed input. The generator itself is a pure step, with no reading or writing of its own, which is what makes it testable in isolation.

Operation names are BUILT rather than borrowed — a verb, the resource noun, then qualifiers, in consistent casing, with a semantic qualifier added for an operation reachable at more than one address so that two paths onto the same operation do not collide. That name becomes the method name of a generated client, which is why it is worth composing carefully.

Structured request and response bodies are hoisted into named components and referenced, and identical shapes are detected by a key-sorted comparison, so the same body authored on different operations collapses onto one component rather than repeating. Bare scalars stay inline, because a reference to a one-line schema is pure overhead.

Security schemes are emitted unconditionally, because every Wildo API authenticates the same three ways, and each operation references the ones that apply rather than describing them again. The error responses the framework owns are written once and referenced from every operation that can return them.

A section with no operations after filtering is omitted rather than emitted empty.

Share application code as versioned modules Tool

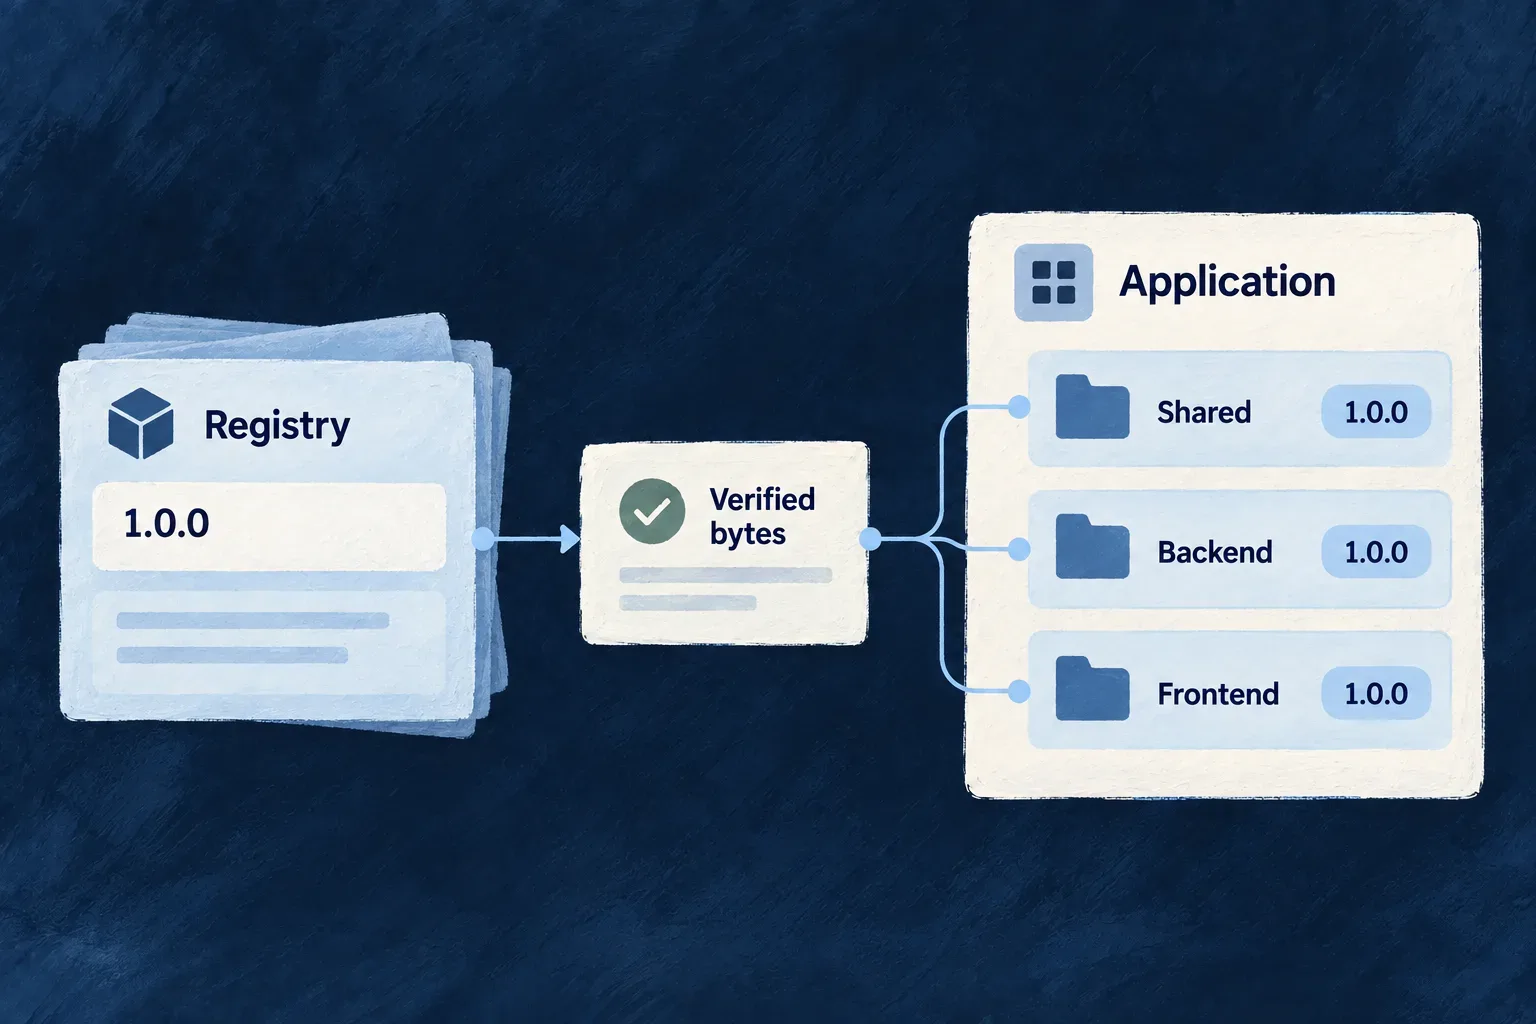
A reusable module packages a piece of an application with the source files that belong together. Shared definitions, backend behavior and interface code can travel in one named version, with a manifest describing where they belong.

Publish it to a registry, then choose the version each application adopts. Wildo verifies the downloaded artifact, places its files in the declared application paths and records that installation for later changes.

Example: Reuse an internal billing extension

A team packages its billing extension across shared, backend and frontend folders. Another application installs version 1.0.0, reviews the added source and connects the extension to its own configuration. A later release is an explicit update, so each application can adopt it at the right time.

A versioned registry artifact is verified and placed in the shared, backend and frontend layers of an application.
For engineers
Declare the files that travel together

Place wildo.module.json at the publishing application’s root, or select another manifest with --manifest. This illustrative manifest packages an existing billing extension. The paths are relative to that application root and must match real source directories:

{
  "id": "acme/billing",
  "version": "1.0.0",
  "description": "Internal billing extension",
  "boundaries": {
    "shared": ["shared-lib/src/modules/acme-billing"],
    "backend": ["backend-lib/src/modules/acme-billing"],
    "frontend": ["frontend-lib/src/modules/acme-billing"]
  }
}

version is an exact semantic version. boundaries can also include specifications, minions and workers. Publish collects files from these declared paths and packages them with the manifest; a manifest with no declared boundary directories is refused. Installation preserves the relative paths in the receiving application rather than moving code into an npm dependency directory.

Choose boundaries that belong to this module. Files outside them are rejected during placement, but a boundary is a placement contract supplied by the publisher, not a sandbox for the code after installation. Review the module as application source.

Publish, inspect, then install

The following illustrative workflow uses a registry already configured and authenticated for publication. The internal registry domain contains module acme/billing; these are separate parts of the add reference.

# In the application that owns the extension.
wildo registry publish --domain internal

# Inspect the published module before adopting it.
wildo registry search --domain internal --query billing
wildo registry info --domain internal --module acme/billing

# In the receiving workspace: note preexisting changes.
git status --short --untracked-files=all

# Adopt the release and inspect tracked changes and new files.
wildo registry add internal/acme/billing@1.0.0
git status --short --untracked-files=all
git diff
git diff --cached

Use --registry when selecting a registry other than the configured default. Public modules support anonymous reads; restricted access and publication use credentials for the selected registry. Authentication is managed per machine, separately from the module files.

The registry domain must already exist and belong to the organization making the publication request. internal identifies that publishing domain; acme/billing identifies the module inside it. Choosing a domain in the command does not create it or grant publishing rights. New modules inherit the domain’s default visibility. Visibility controls access to registry content; it does not define the module’s software license.

The add syntax is <domain>/<moduleId>@<version-or-range>. A range such as ^1.0.0 resolves to a concrete version at installation time. It is not a subscription that changes a running application whenever someone publishes.

Follow the installation record
StageWhat it establishes
ResolveThe registry selects an exact version and returns its artifact digest
DownloadThe client compares the downloaded bytes with that SHA-256 digest
ExtractVerified artifact files are unpacked into a staging directory and the manifest is parsed
Check requirementsBefore placing source, the CLI checks required module versions, authored capability activation and installed framework versions
Place sourceFiles are copied into application source paths allowed by the manifest
RecordThe lock entry keeps the registry, requested range, resolved version, digest and installed paths
Synchronize providersA follow-up sync refreshes provider artifacts; a warning here requires separate attention

The digest verifies that the received bytes match the artifact the registry resolved. Publisher trust and source review are separate decisions; the digest is not a publisher signature.

The lock entry is written after source placement. If that write fails, the command attempts to restore the files it replaced. Provider synchronization follows the recorded installation and can report a warning without undoing it. Check the command result and generated changes before using the module.

Read what this application adopted

The installation record lives at .wildo-saas/wildo-saas.lock.json, under sections.modules.installed. Example installation record, showing selected fields with illustrative values:

{
  "acme/billing": {
    "moduleId": "acme/billing",
    "domain": "internal",
    "version": "1.0.0",
    "requestedRange": "^1.0.0",
    "files": [
      "shared-lib/src/modules/acme-billing/index.ts"
    ],
    "source": "install"
  }
}

The full entry also records the registry binding, artifact digest and installation time. requestedRange records the choice the operator made; version records the exact release adopted. files identifies the application paths managed by the module lifecycle, rather than every file involved in integrating the feature.

Inspect that record from the application root, then run the read-only diagnostic:

node --input-type=module <<'JS'
import { readFileSync } from 'node:fs';
const lock = JSON.parse(readFileSync('.wildo-saas/wildo-saas.lock.json', 'utf8'));
console.log(JSON.stringify(lock.sections.modules.installed['acme/billing'], null, 2));
JS

# Inspect the lockfile shape and recorded file presence without repairing.
wildo registry repair-lockfile

A healthy report means those diagnostics found no inconsistency. It does not establish that local source still matches the published artifact or that the feature works in the application.

Integrate the module into the receiving application

A module’s source files and an application’s runtime bindings are different concerns. Review its shared and frontend registrations, backend discovery, service bindings and required settings. Use composition scenarios when creating new connected structure; do not assume copying a module also creates every host-specific registration.

The manifest can declare prerequisites for adoption. Add, update and repair check them after extracting the verified artifact, before replacing application source or updating its adoption record:

RequirementWhat the CLI checksWhat you still establish
Other modulesRecorded module versions satisfy the declared rangesThe adopted code is registered and works in the application
CapabilitiesKnown capabilities are explicitly enabled in application configurationProviders, credentials and application-specific configuration are ready
FrameworkInstalled framework versions satisfy the declared rangeThe complete application compiles and behaves as expected
npm packagesRuntime and peer requirements are printed as advisoriesAdd the dependencies to the packages that consume them and install them

Framework comparison covers every installed model package reached through the application’s workspace framework dependencies, including distinct versions in different packages. Desired version pins and the CLI’s own installation are not used as proof.

A missing or incompatible module, capability or framework prerequisite stops source adoption with a diagnostic. npm requirements remain advisory. It does not automatically install another module, enable a capability or edit package dependencies. Review and test the resulting application after adoption.

The connected module example follows a generated module through its shared, specification and frontend registrations, backend discovery and existing companion loader. It uses the skeleton layout; an adopted module must be integrated into the receiving application’s actual package paths and service keys. Registry adoption places source files, while composition creates a new connected structure.

Let the application’s development tooling compile the new source, then exercise the feature through its actual interface or API. Registry installation establishes file placement and the install record; application verification establishes that the adopted feature works in its new context.

Update deliberately and inspect source changes

These commands run inside the application that installed acme/billing. Updates use the recorded registry unless overridden:

# Record the workspace state before the update.
git status --short --untracked-files=all

# Adopt a selected later release.
wildo registry update acme/billing@1.1.0

# Inventory all changes, then inspect unstaged and staged differences.
git status --short --untracked-files=all
git diff
git diff --cached

# Remove the installed module when it is no longer needed.
wildo registry remove acme/billing

Compare the status listings before and after adoption. Open every new (??) file in your editor; Git’s diff commands omit untracked content. git diff shows unstaged tracked changes, while git diff --cached shows staged changes. Existing staged work remains visible, so distinguish it from the module’s changes rather than attributing the whole listing to the update. No blanket staging is needed to review the source.

Add and update replace files at the module’s destination paths. Update also removes paths belonging only to the previous version; removal uses the recorded installed paths. Files claimed by another installed module are protected from deletion, while overlapping writes produce warnings. This is not a three-way merge of application edits: preserve deliberate changes in version control and review them when adopting a new version.

Choose between a new release and a repair
ChangeWhat happens
Publish a new versionCreates a distinct release; republishing an existing module version is refused
Move a tagChanges which version the tag selects for a future request; installed copies stay at their recorded version
Withdraw a versionRefuses future resolution and download of that version; it does not remove copies already installed
Update an applicationSelects the requested release; matching version and digest produce a no-op without revalidating host requirements
Repair an installationReapplies the recorded exact version for fixable findings, rather than selecting a newer release

Use wildo registry repair-lockfile --fix only after preserving local edits and reviewing the diagnostic. For a missing-file finding, repair re-fetches the recorded version, extracts its artifact and copies its module files back into the application. Existing files can be replaced too: this is not a missing-file-only restore, and it does not back up the application’s edits. Malformed records, including an invalid artifact digest, require manual correction from a trusted lockfile revision; --fix does not reconstruct them. Repair also reports overlapping writes when another installed module claims the same destination. That warning describes a file replacement, not a merge or protection from overwriting it.

Repair refreshes the recorded digest and file list while retaining the installation timestamp and source field. A withdrawn release cannot be re-fetched through this path. Reinspect the resulting source and verify the application afterward.

The module registry coordinates sharing and version selection. Your application retains responsibility for its own integrations, tests and release timing.

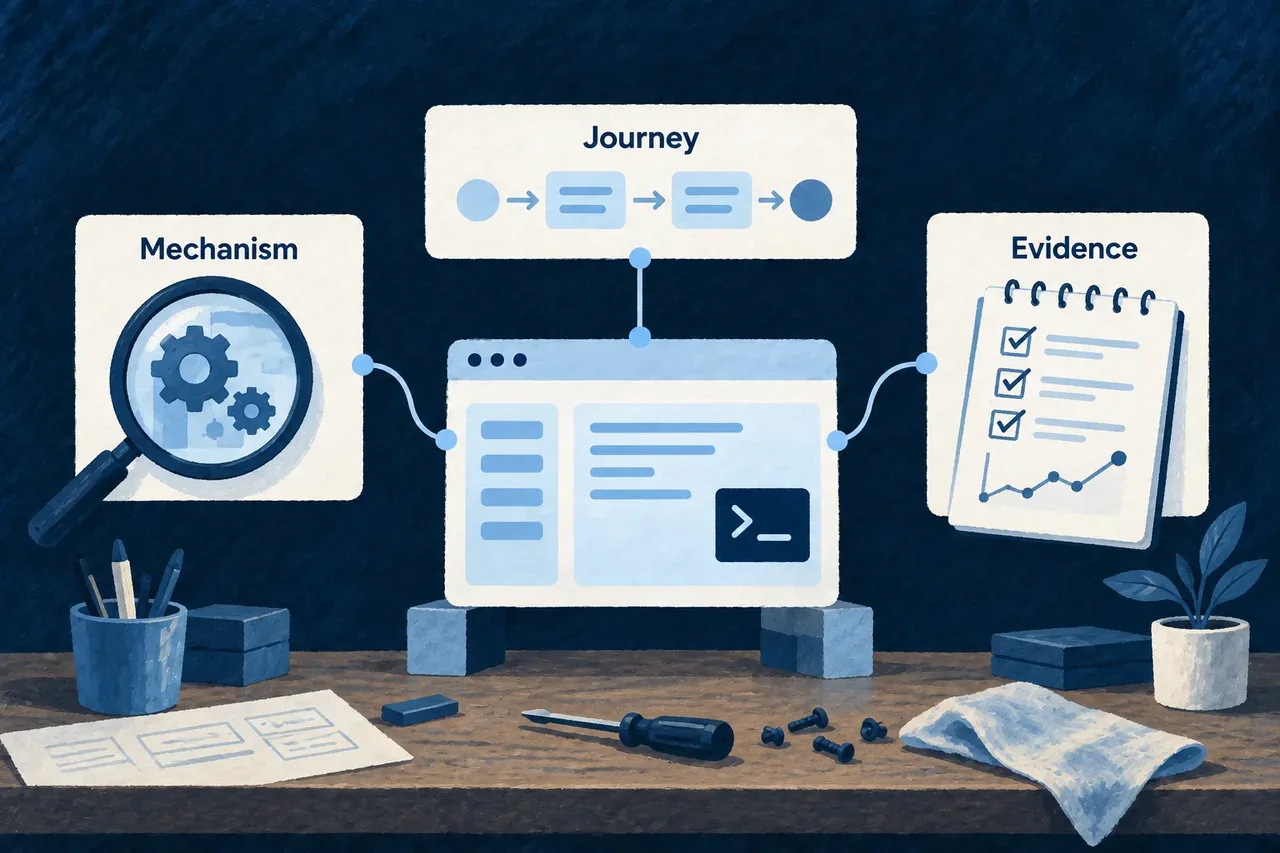
How the framework builds and releases itself

Framework release and publication commands Tool

Releasing the framework is a small set of commands: set the version, sync it across every managed package, publish the packages, publish the image.

Releasing the framework is a sequence of commands: set the version once, write it everywhere, publish the packages, publish the images.

What you decide

The declared publish set lives in the framework configuration, so adding a package or an image to a release is an edit there rather than a flag on the command.

Limits

The combined publish command is a planning command only. It requires a dry-run flag and exits non-zero without one — coordinated cross-registry release orchestration is not wired, so a real release runs the two commands separately.

There is no publish pipeline. The release lane runs from a developer machine, and the framework’s container credential is the one for its registry of record. That is recorded in the release constants as the reason a move to a different registry was reverted, rather than as an aspiration.

The framework version is synchronised across managed framework packages only. The example applications sit outside that surface and carry their own versions.

For engineers

The framework publishes itself with commands rather than with a document someone follows. One version is set once and synchronised into the framework marker and every managed package manifest; the package publish derives its own ordering from the dependency graph; the image publish builds and pushes the declared images under an immutable tag. What gets published is declared in the framework configuration, so the release set is reviewable rather than remembered.

The problem it solves

A framework that ships as several dozen interdependent packages plus a container image has a release that is mostly bookkeeping, and bookkeeping done by hand goes wrong in ways that are expensive downstream. Versions drift apart between manifests. Packages get published in an order where a consumer briefly resolves a version of its dependency that does not exist yet. A prerelease lands on the default distribution tag and reaches every consumer running a plain install, which cannot be withdrawn, only superseded. An alias tag is repointed at an image whose push then fails.

The other half is subtler and specific to a framework built as one workspace. Inside the repository every package declares its third-party dependencies as a wildcard and the real version is pinned once at the root, which is correct for a workspace and meaningless to a consumer, who has no such root. The published manifest has to say something concrete, and what it says has to be derived from that one pin rather than typed a second time.

What it does

The version has one source. Setting or bumping it establishes it; a sync writes it into the framework marker file and into every managed package manifest.

Publishing packages stages a publishable manifest for each declared package, and materialisation is where the workspace wildcard becomes a real range: the root pin is substituted in, exactly for ordinary dependencies and widened for peers — so a consumer keeps the tested version as a floor without inheriting an override it has no way to express.

Publication order comes from the dependency graph, and a cycle is refused rather than published in an arbitrary order. A prerelease version with no explicit distribution tag is refused outright, because the default tag is what a bare install resolves.

Publishing images builds each declared image and pushes it under an IMMUTABLE tag, defaulting to the framework version — and a channel that publishes per commit supplies its own tag instead, because on that channel the commit rather than the version is what makes the artifact unique. Mutable aliases are repointed afterwards, and only after every immutable push has succeeded, by pointing the alias at the published manifest rather than by rebuilding.

Both publish commands support a dry run that prints the exact commands they would execute, and the registry host and namespace are pinned in code, so a framework configuration naming a different pair is refused.

Two coexisting TypeScript compiler lanes Mechanism

The framework can compile a package with either the established TypeScript compiler or the new native one, package by package, with a single switch to roll everything back.

Two compiler versions coexist in the framework repository, and each package is on one of them by an explicit entry in a ledger — so a migration is a per-package promotion and a fleet-wide rollback is one variable.

What you decide

Promote a package by adding its name to the ledger. Roll the fleet back with the override variable — which beats the ledger for every package at once, which is what an operator needs at the moment they need it. A separate compatibility harness measures diagnostic and emit parity between versions before a package is promoted.

Limits

This is framework-repository machinery, deliberately not propagated. The compiler is on the excluded list of dependency alignment, on the stated ground that a compiler version is an application’s own choice — so a generated application pins its own and this ledger says nothing about it.

The parity comparison is keyed on the POSITIONS a compiler rejects rather than on the diagnostic codes it reports, because across a major version the same defect at the same position can be reported under a different code — and a code-keyed comparison reports complete agreement as a regression.

One subsystem stays on the established compiler by decision rather than by omission. Its build inputs are sealed by content and the new compiler’s executable is platform-specific, so sealing what actually runs would give the same source a different identity on a developer machine and on a build server.

For engineers

The framework compiles itself with two TypeScript compilers at once. A ledger names which packages use the newer native compiler; everything else uses the established one. Both are installed side by side under distinct package names, so promoting a package is adding a name to a list, and one environment variable puts the entire fleet back on the compiler that has always worked.

The problem it solves

Changing the compiler of a large codebase is normally an all-or-nothing event. You bump one dependency, every package retargets at once, and whatever breaks breaks together, in packages maintained by different people, with no way to tell a real defect from an artefact of the move. The usual mitigations are worse than the problem: a long-lived branch that diverges, or a per-package build script edit, which means the rollback is as many edits as the migration was and a partial revert is the state nobody notices.

The second problem is quieter. Once two compilers can be installed, the name of the binary stops identifying which one runs. Whichever package wins the shared executable name is an accident of install order, and a build that used the wrong compiler produces output that looks correct.

What it does

A lane is a named pair of a package and an expected identity, resolved by ASKING the package what it is: its own manifest is read, the name is asserted and — for the new lane — the exact version; then the executable that package itself declares is spawned with an argument array. Nothing resolves a bare binary name, and nothing goes through a shell, so a checkout path containing a space is inert. The established lane deliberately asserts no version, because its version is owned by the workspace pin and duplicating it here would create a second authority that drifts.

The compiler is resolved from the invoking package’s own workspace, and a workspace that has not installed the lane’s compiler is REFUSED rather than allowed to borrow one from a parent. That refusal is the boundary that keeps a nested application workspace from silently inheriting the framework’s compiler: resolution walks upwards, the borrowed binary exists and works, and nothing would ever report it.

Incremental build state is scoped per lane, so state written by one compiler can never be read by the other — rewritten by the runner rather than left to each caller to remember, because a shared state file fails as a confusing stale-type error far from its cause.

The lane only decides which compiler emits into the private staging area. The finalizer, the publication journal, the writer lock and the publication ordering are all downstream and unchanged — so a lane flip cannot corrupt a published artifact; the worst case is a package that fails to compile, which fails closed and leaves the previous generation standing.

Because the split is held together by four surfaces that cannot import one another, a dedicated check keeps them in agreement: the declared version against the asserted one, the separate declaration a nested workspace must carry, a ledger entry naming a package that does not exist, a ledger entry for a package with no lane to select, and the executable staying a registered binary of a workspace package.

Watcher-driven build and publication chain Tool

While you work, every package recompiles and republishes itself in the background, and a consumer never sees a half-written build.

In the framework repository, compiling and PUBLISHING are separate steps: each package’s compiler emits into a private staging area, and a finished generation is published in one journaled move that tells supervisors the package is ready.

Limits

There is no retained previous generation. Publication commits the new one and removes the retired one, so rolling a package back means recompiling and republishing it.

A failed or interrupted compile leaves the previous generation in place and publishes nothing — the intended behaviour, and it means a package can be silently one edit behind its source if its watcher died. That is what the currency sweep exists to report, and reading it is a separate act.

The chain is bound to package-local compilation. A mode where one compiler emits into several packages’ directories is rejected at runtime, because it writes past the finalizers that own those directories.

For engineers

Working inside the framework repository, you start one process and every package compiles, finalizes and republishes itself as you edit. The chain has five stages with distinct owners, and its load-bearing property is not speed: a package’s published output directory only ever holds a complete generation, so a consumer importing it mid-edit cannot read a file that is half written.

The problem it solves

A monorepo with dozens of interdependent packages has a build problem that is easy to underestimate. The obvious half is ordering: package B cannot compile until package A has emitted. The expensive half is that the emitted directory is a shared, mutable surface, read by other compilers, by running processes, and by an application whose dependencies are linked into it. Every write to that surface is visible to a reader the instant it happens.

Two failures follow, and both were paid for here. Two processes watching the same output directory interleave their writes and produce truncated files, so a running service crashes on a syntax error in a file nobody edited. And a compiler that kills its own post-compile step when the next compilation starts can interrupt an in-place write between truncating a file and refilling it, leaving a zero-byte module and every link to it empty. Both present as a defect somewhere else entirely: a missing export, a module that cannot be found, a service that will not start. The chain’s design is a response to those, not to build times.

What it does

The watcher fleet is derived, not listed. The workspace graph is read and the packages that declare a watch step are selected — so a new package is watched the day it is created. One status document is written for supervisors to read, and it is enforced that there is only ever one writer, because two writers produce oscillating timestamps and drive every supervisor into a restart loop.

Each watcher runs behind an exclusive lock on its own output directory, and the lock records both the compiler process and the orchestrator that started it — so a holder can be JUDGED rather than trusted. A live holder under a live orchestrator is respected and the newcomer stands down with a distinct exit code; a live holder whose orchestrator is gone is an orphan, and is terminated and replaced. Reclaiming is atomic, so two processes racing the same reclaimable lock cannot both win.

The finalizer runs on the compiler’s success signal. It resolves each package’s internal path aliases and rewrites module extensions in a single in-memory pass, so each emitted file is written exactly once rather than twice with an observable intermediate state. It installs a cooperative interrupt guard before anything else it imports, because installing any signal listener moves the signal onto the event loop and a synchronous write can no longer be torn apart part-way.

Before anything is published, one shared rule refuses a generation containing a zero-byte module — applied at every write path rather than at one of them.

Publication is journaled: the generation is recorded, written into the public directory in place so that linked files survive, and the signal raised that tells supervisors the package is ready. Compiler state files and the writer lock are excluded from what is published, distinguished from what is merely present on disk so that a stray file can still be reclaimed rather than becoming permanent.

A shared foundation deserves continuing evidence.

Wildo centralizes recurring engineering and its maintenance. Your product adds the checks that make its own promises dependable.

Building a B2B product or an internal tool?

Wildo is not self-service yet. Tell us what you have in mind and we will say plainly whether it fits, and what happens next.