
Beyond retrieval: giving application knowledge operable meaning
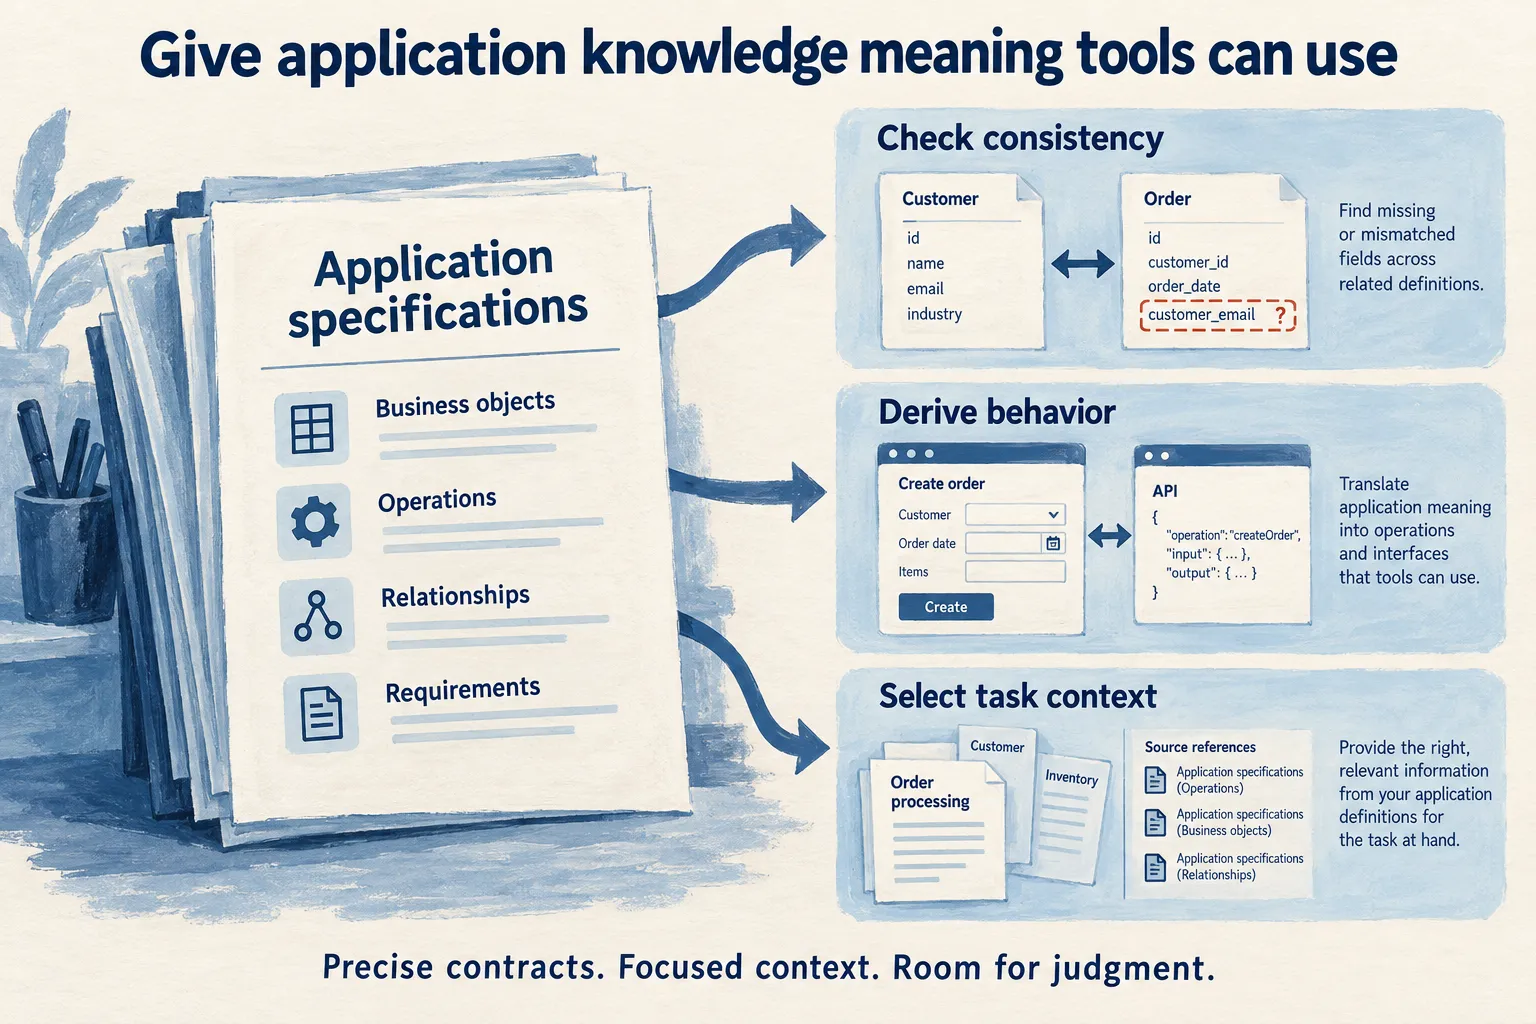
Application knowledge is useful to an agent when it explains what to do. It becomes operable when its meaning also defines what a tool can check, derive or calculate. A requirement written in prose needs interpretation; a declared operation with defined inputs, access rules and relationships exposes questions that software can answer directly.
This distinction matters as applications become more interdependent. An agent must understand not only relevant information, but also which consequences follow from it, which required facts are missing and which distinctions must survive when its context is reduced.
The hypothesis explored here is that a domain-restricted specification language gives application descriptions operable meaning: defined consequences that tools can validate, derive, combine and reduce for a task. For interdependent and changing B2B applications, this can replace repeated interpretation with determinate checks inside an explicit contract. The research question is whether that gain improves execution reliability and total cost once the work of defining and maintaining the contract is included.
The trade is deliberate: give up unrestricted expression at the specification level in exchange for precise meaning within a chosen application domain. Relationships are part of that meaning, alongside types, required choices and rules for deriving consequences. Prose explains intent; agents investigate and interpret; executable contracts settle the questions they formally cover.
The article moves from retrieval to executable meaning, then to context reduction and coordination across levels of an application. An expense-approval change makes the checks and their limits concrete; it is a worked example of the model. First, we examine what retrieval can and cannot establish. Then we define the information a change depends on, follow its consequences and ask what makes the result acceptable.
Complexity is more than the size of the repository
A large collection of independent tasks may be easier to handle than a small set of tightly connected decisions. What matters is how many conditions can change the correct action, how those conditions interact, and how often they change.
Example: changing who can approve an expense
A product introduces a rule: expenses above a threshold require approval from someone outside the submitter’s reporting line. The request sounds like a change to an approval screen. It also affects the authorization behind the action, API callers, delegated approvals, existing pending requests and the evidence recorded when approval occurs.
An agent may find the screen, identify the button and implement its visibility correctly. That is useful progress. It does not establish whether the underlying action enforces the rule, whether delegation bypasses it, or whether the rule applies to requests already awaiting approval.
These questions require different information. Some answers live in code. Others are product decisions that code cannot settle. The same problem can arise with one agent working across several sessions or several agents working at once.
The difficulty grows with the interaction between scope, dependencies, change and uncertainty. Counting files or tokens captures only part of it.
Revisit those questions under a proposed typed approval description. It requires a decision about pending requests, a reference to a reporting-line source and an explicit set of enforcement paths. These are illustrative contract requirements, not a claim that Wildo already provides this particular approval schema.
| Question | What becomes a computation | What remains judgment |
|---|---|---|
| Does the rule apply to pending requests? | Check that an allowed policy choice is present; apply its defined selection rule to the recorded requests. An omitted choice fails validation. | Decide which policy is appropriate, including its business consequences. |
| Can API or delegated approval bypass the rule? | Compare the required enforcement paths with registered bindings. Execute checks for specified actors and conditions. | Establish that the path inventory and test conditions cover the real application. A binding alone does not prove enforcement. |
| Which source establishes the reporting line? | Resolve the required source reference and validate its declared type. Report a missing or incompatible reference. | Decide which source is authoritative and whether its data represents the organization correctly. |
| What evidence permits acceptance? | Compute which declared obligations lack applicable supporting assessments; detect missing results and recorded contradictions. | Assess the adequacy of those obligations and evidence, including risks the contract does not represent. |
The distinction is not simply that the second column requires less inference. Once inputs, meanings and rules are fixed, these checks have determinate results. An absent required policy choice is a contract violation, even if an agent overlooks it. Whether the chosen policy is right for the business remains a different question.
The substantive distinction is between interpretation that can drift without an explicit error and a formal check with a stated correctness condition. Calling this “analog/digital” does not establish a scientific classification of agents: both language interpretation and validation can run on digital machines. The claim we can examine precisely is that a sound check establishes a specified property of the inspected description. It does not establish that the description captures every relevant fact.
The mechanism is explicit semantics and a defined scope of checking. An extensible vocabulary can also have precise consequences when extensions supply defined semantics and satisfy the required checks. For a finite set of approval-policy choices, exhaustive case handling is one straightforward way to ensure that each accepted choice has a defined consequence. To detect a missing enforcement path, it must also define the expected set. A closed list of allowed names alone does not require every member to be present. Requiredness and coverage rules supply that obligation.
For example, if the required paths are interface, direct API and delegation, but bindings cover only interface and direct API, set difference returns delegation as missing. In free prose, no corresponding error appears merely because the sentence about delegation was never written. A reader may notice the omission, but there is no automatic completeness result until an expected set is made explicit. A failed registry read must likewise remain an inspection failure, not be converted into an empty set.
A norm or strict written procedure can define obligations precisely, but applying its prose still requires interpretation. An executable contract turns selected obligations into checks. This difference is visible in established validation languages: SHACL distinguishes allowed properties from minimum-count requirements, so excluding unexpected data and detecting missing required data are separate constraints.1
Reduction becomes useful here too. A task view can retain the governing policy, reporting-line source, required paths and unresolved obligations while omitting unrelated expense fields. Unlike an unconstrained summary, that projection has a stated preservation rule. It is valid for the eligibility task only if the omitted fields cannot change the eligibility decision or its obligations; otherwise the view must expand.
For Wildo, this is the architectural trade being examined: the engine reduces what an application must express by supplying common mechanisms, while the specification framework gives domain declarations richer meaning. Custom behavior and prose remain necessary outside the defined vocabulary. The gain comes from making selected business meaning operable, not merely from storing more links.
What stronger models change, and what the evidence actually says
It would be a mistake to build this argument on an old observation that models lose track of long prompts. Long-context performance has improved substantially. In its report available on 20 September 2026, OpenAI reports 96.3% for GPT-6 Astra on the eight-needle MRCR v2 benchmark at 512K–1M tokens. That is a vendor-reported result under its evaluation settings, and strong evidence against treating historical retrieval failures as a fixed frontier limit.2
That benchmark does not test whether an agent found every governing decision for an evolving application, changed all affected consumers, and verified the resulting behavior. Retrieval over a supplied context and discovering what belongs in that context are different tasks.
An agent also includes more than a model. Its tools, instructions, external records and execution loop affect what it can discover. Three recent results are particularly useful because they challenge a simplistic case for more structure.
Grep can be a strong baseline
In Is Grep All You Need?, Sen and colleagues compare lexical and vector retrieval across agent harnesses. On their 116-question LongMemEval-S subset, Codex with GPT-5.4 reaches 93.1% with inline grep results and 75.9% with inline vector results. Delivering results through files changes the ordering: the corresponding scores are 55.2% and 67.2%.3
There is an important qualification: both methods search dialogue records enriched with structured temporal events by the Chronos preprocessing pipeline. This is not an experiment comparing untouched prose against structured knowledge. It shows that retrieval, preparation and delivery interact, and that dismissing lexical search would create a weak comparison.
Organized files can support substantial investigation
RISE retrieves a bounded workspace of documents that an agent can explore with shell tools. In its 100-query evaluation over 100,000 documents, the GPT-5.4-mini configuration matches direct corpus interaction at 78% accuracy while reporting lower average query cost. The systems have different interaction budgets, so the comparison concerns complete designs rather than an isolated storage-format effect.4
Recursive Language Models offer another approach: keep the long input outside the active prompt and let the model inspect it programmatically, with recursive model calls where useful.5 These approaches show why the fair alternative to maintained structure is an agent that can search, organize evidence and revise its inquiry while working.
Graphs help selectively
Han and colleagues’ comparison of RAG and GraphRAG finds that their relative strengths depend on the task and retrieval design. Graph construction can expose relationships, but can also lose useful detail; retaining access to source passages matters.6
Semantic retrieval should not be reduced to synonym matching either. ReasonIR explicitly trains retrievers for reasoning-intensive relevance and shows that this capability can improve.7 A related document may be useful because it supplies a principle or intermediate step, even when it does not contain the answer verbatim.
These studies concern different tasks, models and evaluation settings. Their scores are not a common leaderboard, and the model cohorts in the 2025–2026 papers are not necessarily the frontier available today. Together, they require a more specific question: when does maintaining explicit relationships add value beyond strong search and reasoning?
Relevant information is not necessarily sufficient information
Research on Sufficient Context separates whether a supplied context supports answering a question from whether a model actually answers correctly.8 The distinction is useful for execution too, although extending it from question answering to consequential actions requires additional care.
In the expense example, an old approval policy is relevant. It may even be accurate about how the application used to work. It is insufficient if the current task depends on a later exception or an unresolved decision about pending requests.
There are therefore several questions to ask of retrieved information:
| Question | What it establishes |
|---|---|
| Does it concern this task? | Relevance: the information may help. |
| Is it the governing version? | Authority and currency: it represents the applicable decision or state. |
| Does it cover the conditions that change the action? | Sufficiency: the decisive constraints are available. |
| Does the implementation satisfy those conditions? | Correctness: the resulting behavior has been checked. |
One search result cannot answer all four merely by ranking highly. An explicit reference to an accepted policy can make the second question easier to inspect. A declared dependency can reveal an affected operation. Neither guarantees that the policy is sensible or that every dependency has been recorded.
A model of the information a change depends on
The proposed model starts with a distinction between what should happen, what has been declared, and what has been observed. It treats a project as related, revisable records rather than as one undifferentiated body of context. This is an engineering proposal to evaluate, not a new mathematical theory or a description of a fully implemented Wildo subsystem.
Give different kinds of information different roles
For the expense-approval example, six kinds of record are useful:
| Kind | Question it answers | Example |
|---|---|---|
| Business intent, | What outcome matters? | Avoid conflicts of interest in expense approval. |
| Governing decision, | Which choice applies, and within what scope? | Above the threshold, approval must come from outside the reporting line. |
| Specification, | What precise contract or acceptance condition follows? | An ineligible approver must be rejected through both the interface and direct API calls. |
| Implementation artifact, | What declaration or code is intended to realize that contract? | The approval operation, eligibility check and interface configuration. |
| Observation, | What did a particular inspection or execution actually reveal? | A compiled operation declares a role; a test request returned a rejection. These are different observations. |
| Evidence assessment, | Which claim does an observation support or contradict? | The direct-call test supports rejection for the tested actor and application state. |
The first distinction is simply this: a decision, a piece of code and a test result are different kinds of information. To keep those roles visible, collect them into a set of records at a particular state:
The disjoint-union symbol means that records have distinguishable roles in this model. It does not require separate files or databases. One source file may supply several records, and a richer system may need additional kinds. Framework guidance remains a separate input: it explains how to investigate or modify these records, rather than establishing the current facts of this application.
An observation is deliberately separate from an evidence assessment. A log entry records something that happened. Whether it supports an acceptance claim depends on the actor, environment, applicable version and conditions exercised. Recording the observation preserves the possibility of challenging that interpretation later.
Name the relationships, not only the categories
Knowing that a record is a specification does not tell us which code implements it or which observation supports it. Named relationships answer those questions. The notation below describes three kinds of link:
An implementation artifact can address several specifications, and a specification can depend on several artifacts. These are many-to-many relations, not a pipeline with one output per input. A declared realizes link records an implementation claim; it is not proof that the claim is true. An assessment records its outcome, including contradiction or inconclusive evidence, rather than treating every linked test as a success.
Other relations connect decisions to intent, specifications to governing decisions, and observations to the artifacts or application state inspected. Each relation needs a defined meaning. “Related to” is often too weak to determine what should be reviewed when either endpoint changes.
Stable identity makes a record findable after its wording changes. Revision and scope establish which version a link refers to. Provenance identifies the source; explicit authority identifies which decision governs. These properties belong to relationships as well as records: an assessment about yesterday’s implementation must not silently become evidence about today’s.
In this model, governing choices are made by the designated decision process. An agent may propose them or identify a conflict, but relevance, recency and repetition do not by themselves turn a proposal into an accepted decision.
Working model: selecting context for a task
An agent needs more than a packet of selected facts. It also needs to know what remains unresolved and how to investigate. For task at project state , these three parts form the proposed context bundle:
Here, contains the available records, typed relationships and their state information. is the selection mechanism. The task context contains three complementary parts:
- : selected information, with its role, scope and provenance. Historical or conflicting records remain identifiable as such.
- : known unresolved questions and obligations, including missing information needed to act.
- : ways to investigate further, such as companion queries, source references, framework guidance and executable checks.
Applicable global constraints belong in the selected context even when their source lies outside the task’s local module. Unknown dependencies can still escape selection; the bundle is a way to expose known uncertainty, not a certificate of completeness.
For the approval change, the task context could include the accepted policy, the existing operation and the relevant authoring guidance. It should also retain “the reporting-line source is unresolved” as an open question. Omitting that question would make the bundle shorter while hiding the reason implementation cannot yet be accepted.
The bundle must be reconsidered when its governing decisions, inspected state or known obligations change. A refresh can preserve valid observations while marking other assessments for review. It should not rewrite an old result to make it appear current.
There is a simple reason selection matters even for an excellent reasoner. Consider two possible project states, and . Let be everything the agent has observed when it must decide, and the set of acceptable final actions for task in state . Suppose:
The agent sees the same information, but the states require incompatible actions. If it must commit without another observation, a decision based only on that information cannot be guaranteed correct in both states. Randomization does not restore that guarantee. Further investigation or escalation can resolve the problem, if the workflow permits it.
In our example, the two states might differ only in whether the new approval rule applies to pending requests. Reading the same screen and API code cannot reveal a product decision missing from both observations.
This is an elementary indistinguishability argument, related to the reasoning used in communication complexity.9 It establishes an information requirement. It establishes neither a token threshold nor a requirement to store that information in a graph. A conversation, a document or a typed record could supply the missing fact.
What explicit structure contributes
“Structured” is useful only when it names something a system can do with the information. A paragraph inside JSON does not, by itself, make a dependency inspectable. A Markdown file with stable identifiers and validated references may provide substantial structure.
For complex work, the useful elements are often modest:
- An identity that survives a change of wording.
- A named relationship, such as an operation implementing a requirement.
- A distinction between a proposal, an accepted decision and a superseded one.
- A source and scope that explain what a record actually represents.
- An acceptance condition that connects completed work to evidence.
These elements support operations that would otherwise require repeated interpretation: following declared consumers, finding unresolved references, selecting the decisions applicable to a task, or checking whether a required output exists.
An instruction such as “check the approval policy before changing this action” describes a procedure. It does not identify the governing policy, record that it changed yesterday, or enumerate the other consumers affected by that change. A skill can query those facts and run checks; the instruction and the records then have complementary responsibilities.
Prose still carries reasons, trade-offs and ambiguity. Search still discovers relationships nobody recorded. The proposed benefit comes from preserving useful results of earlier reasoning so that every subsequent task does not have to reconstruct them independently.
An empty query result needs interpretation too. It can mean that no matching dependency is recorded. It establishes that no dependency exists only if the inspected representation is complete for that question. Explicit structure makes the scope of a check easier to name; it does not make the scope universal.
What an executable check actually proves
Suppose an approval description is , the property being checked is , and is its validator. The soundness obligation is:
The right-hand side means that the description satisfies the specified property under the chosen semantics. For example, every required enforcement path has a correctly typed binding. The implication is a requirement to establish about the checker, not a guarantee obtained merely by giving it a name. A checker that always refuses to pass is sound in this sense but useless; practical value also requires it to accept enough valid cases and finish within a useful budget.
This is the kind of precision formal methods demand. In the small language developed in Software Foundations, progress and preservation together establish that well-typed terms do not reach a stuck state. That theorem concerns the language and rules being proved; it is not a theorem that every typed application meets its business requirements.10
For our expense example, checking a binding is different from proving that the bound implementation rejects every ineligible approver. That stronger property needs an account of execution and its assumptions. A wrong validator, an inaccurate reporting-line source or an incomplete requirement breaks a different part of the argument. Determinism alone is insufficient: a consistently wrong checker remains wrong.
When missing information becomes a computed result
Let be the finite set of required enforcement paths for a particular revision, and the paths with valid bindings in a successfully inspected registry. Missing bindings are exactly:
With interface, direct API and delegation required, but only the first two bound, contains delegation. This is a complete answer to the set-coverage question because the expected set and inspected set are explicit. It does not answer whether a fourth entry path exists outside that inventory or whether the bindings enforce the rule at runtime.
Three different boundaries matter:
| Boundary | What it controls | What it does not establish |
|---|---|---|
| Allowed vocabulary | Which path kinds or policy choices are accepted. | That every required path is represented. |
| Required coverage | Which members must be present for this task and revision. | That the expected inventory covers the real system. |
| Inspection completeness | Whether the relevant registry was read successfully and completely. | That declared bindings behave correctly. |
This also separates schema closure from the closed-world assumption. The OWL 2 Primer explains that, under open-world semantics, an unstated fact may be unknown rather than false. An ontology can have formal semantics without treating absence as falsity.11 Our set calculation needs complete inputs for the scoped coverage question; it does not require a globally closed universe of business concepts. A missing sentence can become detectable too, if an external checklist states that it is required. The operative ingredient is the expectation and check, not whether the file is Markdown or JSON.
When a smaller task view preserves the answer
Now ask whether the approval decision can be made from a smaller view of the application. Let be a modeled state containing the relevant policy, request and actor information. Let be the specified decision, and a reduced view. An exact reduction requires a function on the reduced views such that:
In words: evaluating the reduced view gives the same decision as evaluating the full modeled state. Such a function exists on the image of exactly when:
The argument is short. If two states become the same view, a function of that view must return the same answer for both. Conversely, if every group of states sharing a view also shares an answer, assign that answer to the view. This establishes existence; it does not automatically supply an efficient algorithm or prove that a proposed projection meets the condition.
For the approval rule, omitting receipt color may be harmless if the specified decision never depends on it. Omitting the reporting-line relation is not harmless when two otherwise identical states require opposite decisions. No amount of reasoning over that identical reduced view can recover the lost distinction. The system must retrieve more information, expose uncertainty or decline to decide.
The condition is task-relative. A view sufficient for eligibility may be insufficient for audit evidence or data retention. To preserve those obligations as well, include them in the output being preserved by . Defining that output adequately still requires judgment.
When an approximate view can still be safe
Exact reduction is not always available. Abstract interpretation provides an established theory for sound approximation of program semantics.12 A simpler set-based construction illustrates the relevant obligation here without claiming to implement the full theory.
For a view , let be a nonempty set of modeled states compatible with it, including the actual modeled state. Suppose a computable analysis returns possible decisions and is sound in the following sense:
The analysis may include extra possibilities, but must not exclude a real one. If its result contains only approval, all represented possibilities permit approval. If it contains both approval and rejection, approval has not been established: investigate further or stop. A result of “all possible answers” is sound but offers no useful precision.
This exposes a concrete trade-off. Smaller views may be cheaper to process but less decisive. More expressive checks may be harder to implement or run. Restricting the domain can make useful checks tractable, but restriction alone proves neither efficiency nor correctness.
These are established proof patterns and elementary conditions applied to our example, not new theorems about agents. No proof is claimed here for Wildo’s validators, task reductions or generated behavior. The empirical hypothesis is that engineering useful instances of these contracts reduces agent errors and total work compared with reconstructing the same meaning repeatedly.
Organization theory helps explain the trade-off
Organizations have long faced the problem of distributing work among participants who each hold only part of the information. Their theories do not prove an architecture for agents. They do offer specific mechanisms that can be examined without assuming that an AI system should copy a corporate hierarchy.
Specialization saves work, but communication consumes work
Bolton and Dewatripont model organizations as communication networks. Specialization can reduce information-processing costs, while communication requires the recipient to absorb information. Collaboration is worthwhile when those gains justify the coordination costs.13
The relevant design question for agents is how much work a handoff actually saves. A specialist receiving a clear task, relevant contracts and useful evidence may avoid reviewing an entire application. A specialist receiving a vague summary may have to reconstruct the same background, then communicate it again.
Radner studies a related trade-off between processing capacity and delay in networks of limited-capacity processors. His formal results concern restricted computations, notably associative operations; they cannot be imported as a scaling law for software design.14 They nevertheless make the accounting question explicit: parallel work has costs, and faster completion may require more processing resources.
Coordination follows the dependencies
Malone and Crowston organize coordination around dependencies among activities. Their examples include shared resources and producer–consumer relationships, where an output must arrive at the right time and be usable by its recipient.15
For agent work, this directs attention to the handoff contract. The API implementation and the interface may be individually plausible while disagreeing about who may approve an expense. Sequencing the tasks does not resolve that mismatch. Both need the applicable policy; their integration needs a check of the shared behavior.
This is why decomposition should preserve cross-cutting constraints. A small task is useful when it has a manageable scope and explicit obligations to the rest of the system.
Some knowledge must be obtained where it exists
Hayek’s account of dispersed knowledge distinguishes general knowledge from knowledge of particular circumstances. Its relevance here is the need to obtain local information when making a decision.16
A model may know how an authorization system usually works while lacking the current role configuration of this application. A planning summary may describe an intended resource while the running development environment exposes a different declaration. A local query can answer a question that general expertise cannot settle.
This is an analogy about information access, not an argument that agent systems should reproduce markets or decentralize every decision. Shared constraints may still require common authority and coordinated updates.
A second agent needs a useful difference
Ide and Talamàs provide a particularly relevant caution. In their economic model, AI instances share a fixed knowledge level, so placing AI in both worker and solver roles offers no additional problem-solving knowledge. That conclusion follows from the model’s assumptions, not from an empirical evaluation of today’s multi-agent systems.17
For this article’s proposal, the corresponding design requirement is to give review a distinct contribution: different evidence, a different objective, executable checks, or access to affected consumers. A second invocation may help, but its label does not establish independent judgment. Review should be evaluated by the errors it detects and the cost it introduces.
The organizational theories suggest questions to ask of the same approval change:
| Coordination problem | Consequence for the workflow |
|---|---|
| Communication consumes effort. | Give an implementer the governing rule and its unresolved questions, rather than asking them to reconstruct the entire project history. |
| Work shares dependencies. | Check the interface and API against the same approval contract. |
| Knowledge is dispersed. | Inspect the application’s actual reporting-line source instead of assuming a conventional organization model. |
| Another participant may know no more. | Give review a distinct task, such as testing direct calls and delegation independently of the interface work. |
Why changing direction becomes difficult
A mature organization has accumulated more than information. It has commitments, routines, interfaces, investments and expectations that fit an established way of working. Changing direction requires understanding which of those arrangements remain useful and which now conflict with the goal.
Hannan and Freeman’s theory of structural inertia connects the difficulty of change to the reproducibility that supports reliability and accountability. The same arrangements that make an organization dependable can make reorganization difficult. But size alone does not settle its capacity to change: a large organization may also have more resources to implement a transition.18
The comparison with a small entity is therefore conditional. Fewer coupled commitments can make a change easier to coordinate. Limited resources, concentrated knowledge or dependence on one customer can still make a small organization inflexible. For agent systems, repository size is similarly an incomplete proxy: the cost of changing a decision depends on what relies on it and how those dependencies are maintained.
Knowledge can preserve an old architecture
Henderson and Clark distinguish knowledge of components from knowledge of how components fit together. Their study of architectural innovation explains why established firms can struggle with a change in relationships even when much of their component expertise remains useful. Architectural knowledge becomes embedded in the organization’s information-processing arrangements.19
This suggests a hypothesis for agents working with accumulated project records. If plans, examples and summaries repeatedly express an earlier direction without identifying which decisions were superseded, later tasks may keep reconstructing that direction. Additional records could reinforce an obsolete interpretation rather than resolve it.
That proposed mechanism needs its own experiment. It is not a claim that information has physical momentum, or that more information necessarily makes an agent less adaptable. Accurate change records may do the opposite. The question is whether the knowledge system preserves the history of a decision while making its current authority clear.
Explicit structure can help by making those commitments identifiable and their relationships inspectable. Its advantage here is operational expressivity: a tool can ask which declared decisions an operation depends on, or which evidence a changed contract calls into question. This is different from saying that structured data can express more meaning than natural language. A rigid schema can omit new relationships and preserve the old architecture just as effectively as a stale document.
A change has a scope that must be discovered
Engineering change research studies how an initiating change can create consequences in connected components. Maier and colleagues simulate successive propagation and rework using dependency matrices with likelihood and impact information. Their model is useful for thinking about connected changes; its simulated durations and probabilities are not measurements of agent-driven software development.20
Start with the changed decision. Follow the records that may depend on it, then the records that may depend on those. The purpose is to discover what needs review before deciding what needs modification.
Represent those possible consequences as a finite, fixed graph . Its nodes are the records introduced earlier. A link means that changing may require reviewing . Starting from the changed records , expand the review set:
Each round adds the recorded dependents of elements already reached. The process stops expanding when . Because this snapshot is finite and elements are only added, that fixed point is reached after at most rounds that add an element.
The direction follows the meaning of the relationship. For example, an implementation points to the specification it claims to realize, but changing that specification sends the review in the opposite direction, back to the implementation. Impact links therefore cannot be obtained by following every stored arrow indiscriminately.
This is graph reachability, not a formula for the probability or cost of change. Membership means “review this,” not “modify this.” The closure is only as complete as the recorded graph. New dependencies discovered during investigation require the scope to be reconsidered.
In the expense example, a revised eligibility decision can lead to reviewing a requirement, its operation contract, the interface using that operation and the tests supporting it. Some remain valid. Others require changes. Existing evidence must be reassessed against the changed behavior rather than silently reused.
The connection to Wildo: intent, introspection and framework knowledge
Wildo provides a concrete setting in which to apply these ideas. Its mechanisms answer complementary questions: what the application is intended to do, what its declarations expose, and how the framework’s contracts should be used.
The following account is grounded in the implementation inspected for this article. It illustrates an engineering approach; it is not a comparative experiment establishing that Wildo outperforms another agent system.
Specifications preserve product intent and declared relationships
Wildo’s application specifications give product concepts such as requirements and roadmap phases explicit identities. Where a relationship is declared, tools can inspect it without inferring the connection afresh from similar wording.
A small example shows the difference. If a roadmap phase still refers to a requirement that has been removed, the cross-family coherence report can identify the unresolved reference. It separately represents supported coverage questions, rather than treating every missing connection as the same kind of error.
This check does not decide whether the remaining requirements describe a good product. It makes a specific inconsistency visible so that human or agent judgment can address its meaning. The report also distinguishes absent or unreadable input families; its findings must be interpreted within that scope.
Companion introspection exposes views of the application
The development companion offers a catalog of queries. An agent can discover the available views and ask for a resource registry, resource specifications or specification artifacts. This gives the investigation explicit entry points into the application’s structure.
For example, from an application workspace with its companion running:
# Discover the queries available from this companion.
wildo context list

# Inspect declared resources and their specifications.
wildo context info resources-registry
wildo context info resource-specifications

# Check supported relationships across specification families.
wildo context coherence
These are inspection commands, not a transcript of a run reported here. The CLI prints provenance alongside its payload. In particular, introspection reads compiled application packages: source edits not yet emitted are not represented, and a successful response does not establish build freshness or production behavior.
That distinction is essential. Introspection supplies information about the application as observed through a particular mechanism. It should guide further source inspection and verification, rather than replace them.
The coding-task dispatch mechanism already uses this idea in a limited, concrete way. It supplies the task’s objective, target, expected outputs and references, together with a menu for further queries. When available, it adds a view of the target module’s registered resources and fields, plus a relevant portion of the domain plan. The derived reads are best-effort; the coding agent can investigate further if they are unavailable.
This combines a prepared starting context with discovery during execution. It does not claim to compute an optimal or complete context automatically.
Framework knowledge explains how to use what was found
Knowing that a resource exists does not explain how to extend it correctly. That is the complementary role of framework knowledge.
Wildo combines authored skills and guidance with references extracted from marked source sections. Registered topics connect those extracts to the guidance that uses them. The generator assembles a candidate package, runs validation, and publishes that package for consumers. The loader can expose a catalog of skill names and purposes, allowing a caller to select guidance before loading its details.
This directly connects instructions to the framework surfaces they explain. It also clarifies why skills remain valuable: they express procedures, reasoning and conventions. The surrounding identifiers, source references and package structure make those instructions discoverable and maintainable.
Generation is still a maintenance process. Extracting a current signature does not automatically correct an outdated explanation, and package validation cannot establish that every recommendation is semantically right. The framework guidance and the application view need to be interpreted together.
The correspondence with the proposed record types has important boundaries:
| Proposed model role | Wildo mechanism discussed here | What must still be established |
|---|---|---|
| Intent, decisions and specifications | Application specification families and supported references. | No claim that every proposed decision state or relation in this article exists as one canonical schema. |
| Implementation artifacts and observations | Registered declarations exposed by companion queries, plus source inspection. | An introspection result describes the inspected compiled state; executing behavior is a separate observation. |
| Investigation access | The live-query menu, task preparation and compiled framework guidance. | The proposed three-part context bundle is a design model, not the literal current dispatch contract. |
| Evidence assessments and acceptance | Coherence checks establish specific declared-reference findings; behavioral checks address other claims. | A complete cross-level evidence ledger and the acceptance rule below are proposals here, not asserted end-to-end automation. |
The connection to the research is precise. Specifications can preserve relationships that otherwise have to be rediscovered. Introspection can reduce uncertainty about the application being changed. Framework knowledge can reduce repeated reconstruction of how its mechanisms work. Their value depends on whether those inputs are accurate, available and used effectively.
Readers can inspect these parts of the approach in application specifications, the development companion and CLI, and framework knowledge.
Recursive inspection across levels of the application
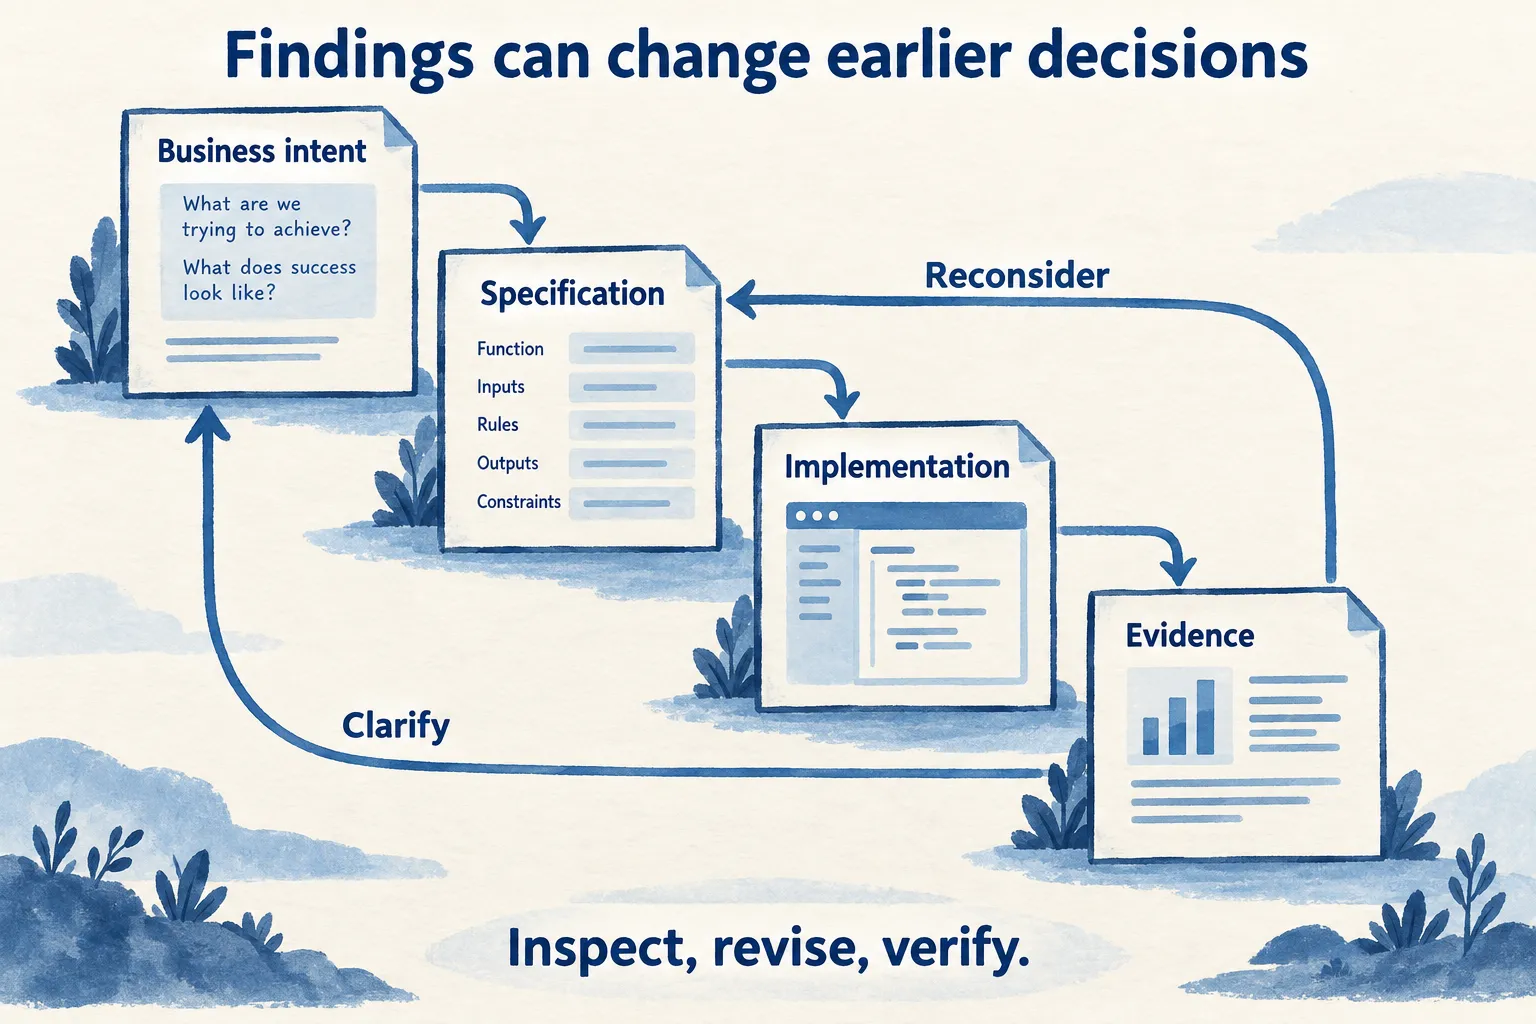
There are two kinds of recursion in the proposed approach. Within a level, following one dependency can reveal another. Across levels, a change in business intent can alter specifications, implementation and the evidence needed to accept it. Findings at a later level can also force an earlier decision to be revisited.
Example: an approval policy that the available data cannot enforce
The new business rule requires an approver outside the submitter’s reporting line. A specification records that constraint. Inspection then reveals that the application has no authoritative reporting-line relationship. Implementation cannot safely invent one. The finding returns to the specification and product decision: establish that information source, revise the rule, or leave the change unresolved. Once a choice is made, the affected contracts and acceptance checks can be reconsidered.
The next context should therefore reflect what the investigation learned. Continuing from the original brief alone would preserve the assumption that the required information already exists.
The practical loop is: inspect the current state, revise what the findings justify, then inspect again. A revision may change an implementation or reopen a product decision. To express that loop, let represent the records and relationships defined above, including their revisions and unresolved obligations, at iteration , and let be the accepted change objective:
Here, contains observations and unresolved questions. Inspection combines relevant queries, source investigation and checks. Revision includes interpretation, authorized decisions, changes and recording their consequences. It may leave a question open or require a new objective. These operators describe responsibilities; they are not deterministic functions currently implemented by one Wildo service.
Companion introspection can support the observation step by exposing application declarations after the relevant changes have been emitted. Framework knowledge helps interpret the contracts and choose how to modify them. Specifications preserve the intended relationships. Behavioral checks supply a different kind of evidence about the result. None of these inputs should impersonate the others.
Acceptance closes obligations, not just a traversal
Finishing the search is not the same as finishing the change. Acceptance requires a reviewed scope, no unresolved blockers and suitable evidence for each obligation.
Let be the explicit obligations for task at the state submitted for acceptance, its known unresolved blockers, and the evidence assessments offered for that state. A proposed acceptance rule is:
ScopeConfirmed asks whether the obligations cover the objective and applicable constraints. The designated reviewer checks that scope; the implementation’s chosen tests do not define it.
Supported asks whether the evidence applies to the obligation, the relevant revisions and the environment. Material contradictions must be resolved. Some obligations require human judgment; others admit executable checks. An unrun test or a declared implementation link is not a supporting result.
For the expense change, evidence must match the question being decided:
| Observation or finding | What it establishes | What remains open |
|---|---|---|
| The interface hides approval from an ineligible actor. | The observed interface path reflects the restriction. | Whether a direct API call also rejects that actor. |
| A direct API request is rejected in the tested state. | That actor was rejected through that path under those conditions. | Delegation, other actors and any untested policy conditions. |
| No authoritative reporting-line source has been identified. | The investigation has found an unresolved input. | How eligibility can be determined; implementation must not invent the relationship. |
| A test passed before the policy or implementation changed. | A historical result is available. | Whether it still supports the current obligation. |
An observation is retained even when its relevance to acceptance changes. The assessment is what must be reconsidered.
This is a proposed acceptance policy, not a computable guarantee of global correctness. The obligation set can itself be incomplete. Independent review and investigation remain necessary, and discovering a missing obligation reopens the relevant assessment. Contradictory goals or unavailable information can require escalation rather than another automatic iteration.
The intended benefit is a context that evolves with the work, including upward corrections to assumptions. Whether that reduces the cost of changing direction must be measured, along with the effort needed to keep the cross-level relationships accurate.
Structure has to earn its maintenance cost
The remaining question is economic: does preserving these relationships save more work than it creates? Every maintained representation creates work. Someone must decide which relationships matter, update them when the product changes, and reconcile them with implementation. A stale, confidently presented record can mislead more efficiently than an obviously incomplete note.
Count the initial setup, the updates and the work of performing each task. For a sequence of tasks, that gives:
Here, is an approach being compared. Setup includes preparation of its knowledge sources. Updates include keeping them useful as the project changes. Execution includes retrieval, interpretation, implementation, review and rework. Costs must use a declared basis, such as elapsed time or money, with human effort reported as well.
This is accounting notation, not a measured crossover curve. It applies to text-based approaches too: curated documents, search indexes and reusable notes also need maintenance.
Maintained relationships become attractive when their reuse and checks save more than their upkeep costs, at an acceptable level of reliability. For a short, isolated task, reconstruction may be cheaper. For repeated changes that cross the same boundaries, preserving those boundaries may have more value. Where the balance moves is an empirical question.
How to test the thesis fairly
The experiment should begin with changing application tasks, rather than only questions about a static corpus. The expense-policy example suggests a useful family: alter a decision, ask for an implementation, then test both the visible feature and its affected consumers.
All conditions should receive the same underlying facts and use the same model, reasoning effort and acceptance criteria. The comparison should separate information representation from extra curation, extra tool access or a stronger controller.
| Approach | What the agent can use |
|---|---|
| Iterative text search | Repository files and guidance, lexical search, repeated inspection, and notes written during the task. |
| Hybrid retrieval | The same facts, with semantic retrieval and reranking in addition to lexical tools. |
| Structure built during execution | The same sources, with the agent allowed to construct working maps, tables or dependency records as needed. |
| Maintained relationships and executable contracts | Reusable identities and links, requiredness and coverage validators, defined derivations, and task views with explicit preservation checks. Original sources remain accessible. |
The first three conditions must be strong implementations, not deliberately impoverished prompts. The last condition must pay for creating and updating its additional representations. Errors deliberately introduced into those representations should be part of the evaluation too.
Within the maintained-contract condition, compare links and retrieval alone against the same records with executable validation and derivation enabled. Test reductions against the full contract for the stated task: removing irrelevant information must not change the checked decision or hide an obligation. This separates the value of operable meaning from the value of recording relationships. Charge the condition for defining the vocabulary, validators, derivations and preservation checks, including their maintenance.
To isolate the effect of information organization, begin with one agent. Study delegation and review separately, so that a gain from extra reasoning is not incorrectly attributed to structure.
Vary information volume, dependency coupling, change frequency and task duration independently where possible. Then measure whether the agent obtains the decisive facts, uses the applicable versions, identifies unresolved decisions and produces correct integrated behavior. Record latency, tokens, human maintenance and rework alongside those outcomes.
“Insufficient” can then have a measurable meaning: an approach fails a predefined reliability target within a stated resource budget on a specified distribution of tasks. There need not be one sharp complexity threshold, and any observed boundary may move with better models or tools.
The thesis would be weakened if strong search-based agents achieve comparable outcomes at lower total cost, if they reconstruct useful structure cheaply enough, or if maintained records introduce more staleness than they prevent. It would gain support if operable contracts repeatedly detect omissions, preserve the constraints needed by reduced task views and improve downstream behavior after those costs are included. If executable meaning adds no benefit over links and strong retrieval, that would weaken this stronger version of the hypothesis.
To test the inertia hypothesis, hold information volume constant while varying dependency coupling and the presence of superseded decisions. Compare an isolated change with one that crosses intent, specifications, implementation and evidence. Measure recurrence of obsolete assumptions, time to restore consistency, missed consequences and the effort required to maintain the records. Also test whether incomplete or rigid relationships make adaptation worse.
Acceptance must be checked against independently specified requirements and actual behavior. A system should not receive full credit merely because its output agrees with the same incomplete model that guided it.
Preserving what the next task needs to know
The central proposal is to give selected application knowledge operable meaning. A domain-specific contract can turn some questions into determinate checks, expose missing obligations and support reductions that preserve the distinctions a task needs.
Wildo approaches this from both ends: the engine reduces how much common application behavior must be expressed, while specifications and framework knowledge give the remaining declarations richer, domain-specific meaning. Introspection makes application declarations available for investigation. Prose, search and human judgment remain necessary for intent, discovery and questions outside the executable contract.
The aim is to preserve useful reasoning across changes and participants while keeping room for discovery. Stronger models can make some machinery unnecessary. They can also make better use of well-maintained information. A sound architecture should allow both possibilities, and make its value measurable.
Definitions
- Agent
- A system that uses a model, instructions, tools and an execution loop to pursue a task. Results depend on the whole system, not only the underlying model.
- Task context
- The information available to an agent for a particular task at a particular point. The proposed bundle includes selected information, known unresolved questions and ways to investigate further. External project records can be much larger than this view.
- Selection mechanism
- The process that obtains task information through search, explicit queries, source inspection, summaries or additional investigation. It can change as the agent learns more.
- Sufficient context
- Information that supports answering the specified question. In this article’s proposed extension to execution, it includes the governing conditions needed to choose an acceptable action. Correct reasoning remains a separate requirement.
- Explicit structure
- Identities, relationships and states represented through an agreed contract that tools can inspect or validate. It can live in repository files, databases or other formats, and can contain substantial prose.
- Introspection
- Inspection of a system’s exposed structure or state. The Wildo examples here concern companion views of compiled application declarations, not proof of production behavior.
- Framework knowledge
- Guidance about a framework’s contracts, conventions and authoring procedures. In Wildo, authored skills and source-derived references are assembled into a consumable package; application-specific facts have separate sources.
- Evidence assessment
- An interpretation linking observations to a specified claim, outcome, scope and relevant revisions. An observation may support one claim while leaving another unresolved.
- Acceptance obligation
- A condition the scoped change must satisfy. The set is reviewed against the objective and applicable constraints; it is not defined solely by the implementation’s chosen tests.
- Organizational inertia
- Resistance or delay in changing established arrangements relative to changing demands. Here it motivates an investigation of commitments, routines and dependencies; it is not defined by information volume or organization size alone.
- Recursive impact analysis
- Repeatedly following consequences within a dependency network and between intent, specifications, implementation and evidence. A discovered consequence can reopen earlier assumptions; reachability alone does not establish a required modification or a correct outcome.
- Coordination
- Managing dependencies among activities: shared inputs, usable outputs, timing, constraints and integration. Splitting work creates a need to examine these dependencies.
References and notes
-
W3C. Shapes Constraint Language (SHACL), Recommendation, 20 July 2017. Minimum cardinality and closed shapes distinguish missing required values from disallowed properties. This is a validation precedent, not evidence of comparative agent performance. ↩
-
OpenAI. GPT-6 Astra: A new generation of intelligence. Long Context evaluation table, consulted 20 September 2026. Vendor-reported MRCR v2 results, maximum score at any evaluated effort; not an independent test of application engineering. ↩
-
Sahil Sen et al. Is Grep All You Need? How Agent Harnesses Reshape Agentic Search. Version 1, 14 May 2026, §§3–4 and Table 1. Preprint; a 116-question subset with Chronos-enriched session records. Results concern retrieval and harness combinations. ↩
-
Shengyao Zhuang et al. Towards Retrieving Interaction Spaces for Agentic Search. Version 1, 5 June 2026, §§3–5 and Table 1. Preprint. The cited comparison uses GPT-5.4-mini at medium effort; interaction budgets differ between systems. ↩
-
Alex L. Zhang, Tim Kraska and Omar Khattab. Recursive Language Models. Version 3, 11 May 2026. External context inspection and recursive calls provide a counterexample to treating the active prompt as the agent’s entire information environment. ↩
-
Haoyu Han et al. RAG vs. GraphRAG: A Systematic Evaluation and Key Insights. Version 3, 4 March 2026, §§4–5. Task-dependent retrieval and summarization comparisons; the experimental model cohort is older than the research snapshot used for this article. ↩
-
Rulin Shao et al. ReasonIR: Training Retrievers for Reasoning Tasks. Version 1, 29 April 2025, §§4–5. Evidence that learned retrieval can support reasoning-intensive relevance, not a measurement of current frontier-agent execution reliability. ↩
-
Hailey Joren et al. Sufficient Context: A New Lens on Retrieval Augmented Generation Systems. Version 3, 23 April 2025, §§3–4. The distinction concerns question answering. Its extension to actions, governing decisions and current state is proposed here. ↩
-
Tim Roughgarden. Communication Complexity (for Algorithm Designers), 2015. Lecture 2: Lower Bounds for One-Way Communication Complexity. Formal examples distinguish computational ability from information received. The project-state expression in this article is our explanatory formulation, not a published bound on agent context. ↩
-
Benjamin C. Pierce et al. Software Foundations, Volume 2, Types: Type Soundness. The chapter proves safety for its defined typed arithmetic language through progress and preservation; it does not establish business correctness. ↩
-
W3C. OWL 2 Web Ontology Language Primer, Second Edition, 11 December 2012, §2: What Is OWL 2?. Explains the open-world treatment of unstated facts and distinguishes ontology semantics from syntax-conformance constraints. ↩
-
Patrick Cousot and Radhia Cousot. Abstract interpretation: a unified lattice model for static analysis of programs by construction or approximation of fixpoints. POPL 1977. Authors’ paper page and detailed summary. Establishes a theory of consistent abstractions of program semantics; the decision-set construction here is an illustrative soundness condition, not a claim that an agent summary implements that theory. ↩
-
Patrick Bolton and Mathias Dewatripont. The Firm as a Communication Network. Quarterly Journal of Economics, 1994. Authors’ institutional research record and abstract. Specialization is considered alongside the cost of absorbing communicated information. ↩
-
Roy Radner. The Organization of Decentralized Information Processing. Econometrica, 1993. Author-hosted paper, introduction and §§2–5. Its processing-capacity and delay results have restricted computational assumptions; they are not an empirical law for LLM teams. ↩
-
Thomas W. Malone and Kevin Crowston. The Interdisciplinary Study of Coordination. ACM Computing Surveys, 1994. Author-hosted paper, §2 and Table 1. The article applies its dependency perspective to agent handoffs; that application is an interpretation. ↩
-
F. A. Hayek. The Use of Knowledge in Society. American Economic Review, 1945. Essay, especially §§III–V. Used for its treatment of dispersed, situation-specific knowledge, not as proof of a particular agent architecture. ↩
-
Enrique Ide and Eduard Talamàs. Artificial Intelligence in the Knowledge Economy. Journal of Political Economy, 133(12), 2025. Published article, §III.A. The fixed, shared AI-knowledge assumption explains the result discussed here; actual agents can differ in context, tools and execution. ↩
-
Michael T. Hannan and John Freeman. Structural Inertia and Organizational Change. American Sociological Review 49(2), 149–164, 1984. Published paper, especially the discussion of size and reorganization, p. 159. Author-uploaded record. Organizational theory, not an agent benchmark. ↩
-
Rebecca M. Henderson and Kim B. Clark. Architectural Innovation: The Reconfiguration of Existing Product Technologies and the Failure of Established Firms. Administrative Science Quarterly 35(1), 9–30, 1990. Original paper. Its component/architectural knowledge distinction motivates the proposed transfer to project records; it does not test LLM context. ↩
-
Jakob F. Maier et al. Simulating progressive iteration, rework and change propagation to prioritise design tasks. Research in Engineering Design 25, 283–307, 2014. Original paper, §§3.3.3 and 6.3. A simulation study with stated assumptions about propagation and rework. The reachability recurrence here is a simpler explanatory model, not its probabilistic algorithm. ↩